Two models, identical prompts, ten capability categories. One is a 7B research-licensed model running 40 bf16 steps on a DGX Spark; the other a 9B non-commercial model running 4 MLX steps on a Mac. This is what happened when we asked both to do the same jobs.
| Models | Qwen-Image-2.1 7B vs FLUX.2 Klein 9B |
| Slots | 10 capability categories, 26 prompt/seed jobs |
| Hardware | DGX Spark GB10 (CUDA 13, aarch64) vs Mac Studio M3 Ultra (mflux/MLX) |
| Prompts | Byte-identical — both runners import the same matrix.py |
| Scoring | 0–5 on prompt adherence, text correctness, anatomy, realism, artifacts |
| Overall | Qwen 4.49 / 5 · FLUX 4.19 / 5 |
1. High-level comparison
The bottom line first
Qwen wins the headline number by 0.30 points — but that gap is almost entirely text. Strip out the two text slots and FLUX is ahead. Qwen is best understood not as “the better image model” but as a text-rendering specialist that also happens to do images. It also ships under a research-only licence, which matters if you intend to use the model itself commercially (see section 5).
Category scorecard
| # | Category | Qwen | FLUX | Winner |
|---|---|---|---|---|
| 1 | Text rendering — English | 4.78 | 4.06 | Qwen |
| 2 | Text rendering — Hindi (Devanagari) | 4.83 | 3.33 | Qwen |
| 3 | Humans — portrait | 4.38 | 4.62 | FLUX |
| 4 | Humans — full body & pose | 4.25 | 4.12 | tie → FLUX |
| 5 | Humans — groups & diversity | 4.38 | 4.12 | Qwen |
| 6 | Humans — action / expression | 4.38 | 4.38 | tie → FLUX |
| 7 | Reference-image editing | 4.38 | 4.06 | Qwen |
| 8 | RGBA / transparent output | 4.29 | 4.00 | Qwen |
| 9 | Aspect ratios & speed | 3.56 | 5.00 | FLUX |
| 10 | Prompt adherence stress | 5.00 | 5.00 | tie → FLUX |
| ALL SLOTS | 4.45 | 4.19 |
Ties are decided in FLUX’s favour when the margin is under 0.15 — it is faster and its outputs carry fewer restrictions. Without that rule the raw means are Qwen 4.45 / FLUX 4.19.
What each model actually buys you
| Qwen-Image-2.1 | FLUX.2 Klein | |
|---|---|---|
| English text in pixels | 4/4 strings letter-perfect | 0/4 — every one has a character slip |
| Devanagari | 55/55 characters correct | 55/55 wrong (confident gibberish) |
| Identity preservation (edits) | 5/5 | 3/5 — re-makes the face |
| Instruction-following (edits) | 3/5 — ignores garment detail | 5/5 |
| Multi-reference (2 people) | Yes | Impossible — single-ref API |
| Native alpha channel | Yes, one pass | No — needs rembg, leaves green fringe |
| Landscapes / aspect ratios | Weak (2/5) | Excellent (5/5) |
| Skin / portrait realism | Good, smoothed | Best in test |
| Speed (median) | 51.8 s/image | 28.2 s/image |
| Speed at 9:16 tall | 104 s | 231 s |
| Licence | Research only — no commercial use | Non-commercial 9B weights; outputs cleared for commercial use |
The three things Qwen wins outright
- English text you can trust. Including a 38-character headline rendered exactly at two different
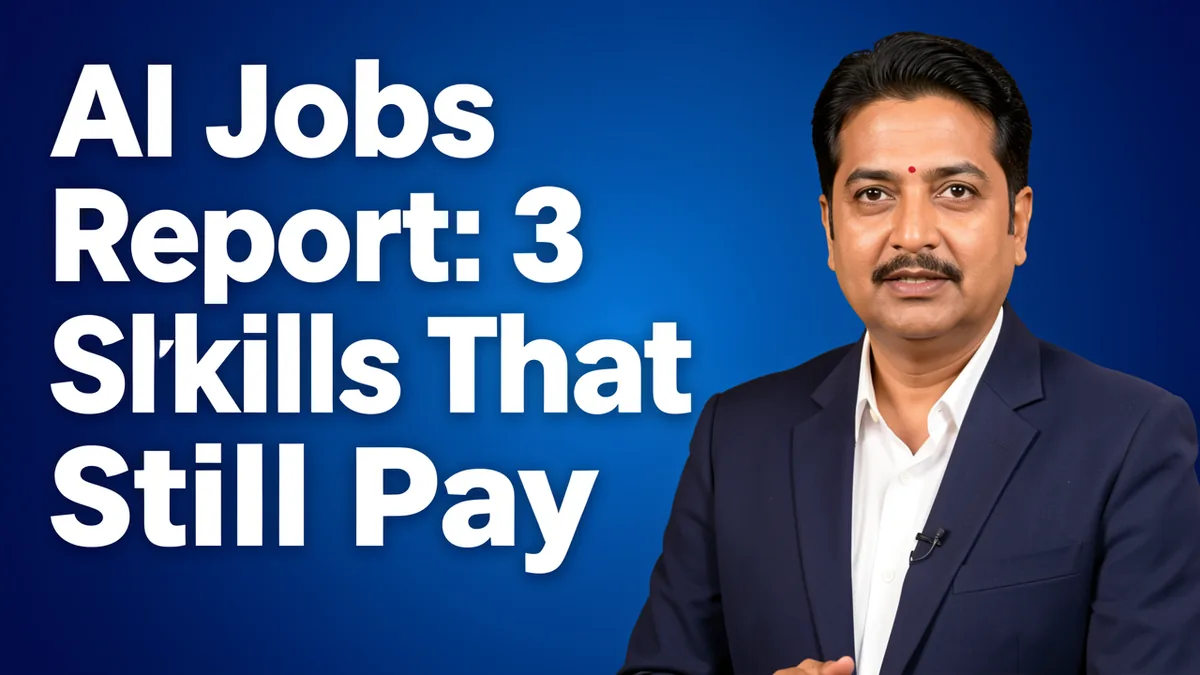
seeds. FLUX’s errors (
3 SIkills,Skills Th,Technlogies,latancy) are all single-character slips in otherwise crisp typography — which is worse, not better, because the image looks right until a human reads it. - Devanagari at all. Not a quality gap — a capability gap. FLUX emits Devanagari-shaped noise, crisply and confidently. Correct nuqta, correct matras, correct shirorekha.
- Multi-reference identity. Two named people in one frame. FLUX’s edit endpoint accepts exactly one reference image, so this task cannot be expressed through it at all.
The things FLUX wins
Portraits and skin texture, landscapes, every aspect ratio, edit instruction-following, speed, deployment, and output rights. Ties go to FLUX, and most slots were ties.
2. How the test was run (fairness notes)
- One shared prompt source. Both runners import
matrix.py, so neither model ever saw a prompt the other did not get. Two deliberate differences were forced by the models themselves:- RGBA (slot 8): Qwen got the literal transparency wrapper; FLUX got the same subject on a flat
chroma-green field and was cut with
rembg -m u2net, because FLUX cannot emit alpha. - Slot 7c: Qwen got two references; FLUX got one, because its edit endpoint accepts exactly one.
- RGBA (slot 8): Qwen got the literal transparency wrapper; FLUX got the same subject on a flat
chroma-green field and was cut with
- Not apples-to-apples on compute. Qwen runs 40 bf16 steps on a GB10; FLUX runs 4 MLX steps on an M3 Ultra. Timings are reported as measured, not normalised.
- Both models floor requested dimensions — Qwen to a multiple of 32, FLUX to a multiple of 16. Ask for multiples of 32 and neither surprises you.
- Scores are hand-assigned 0–5, generated into tables by
scores.py. Every image below is the untouched output of that run.
3. Round by round
Slot 1 — Text rendering, English
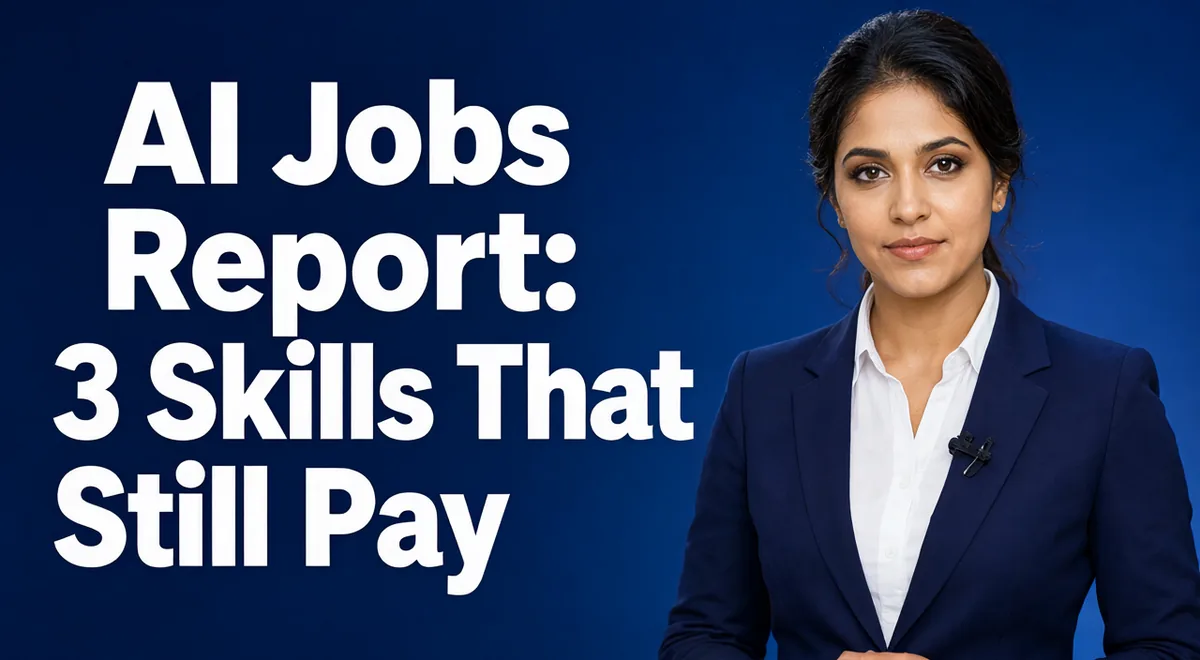
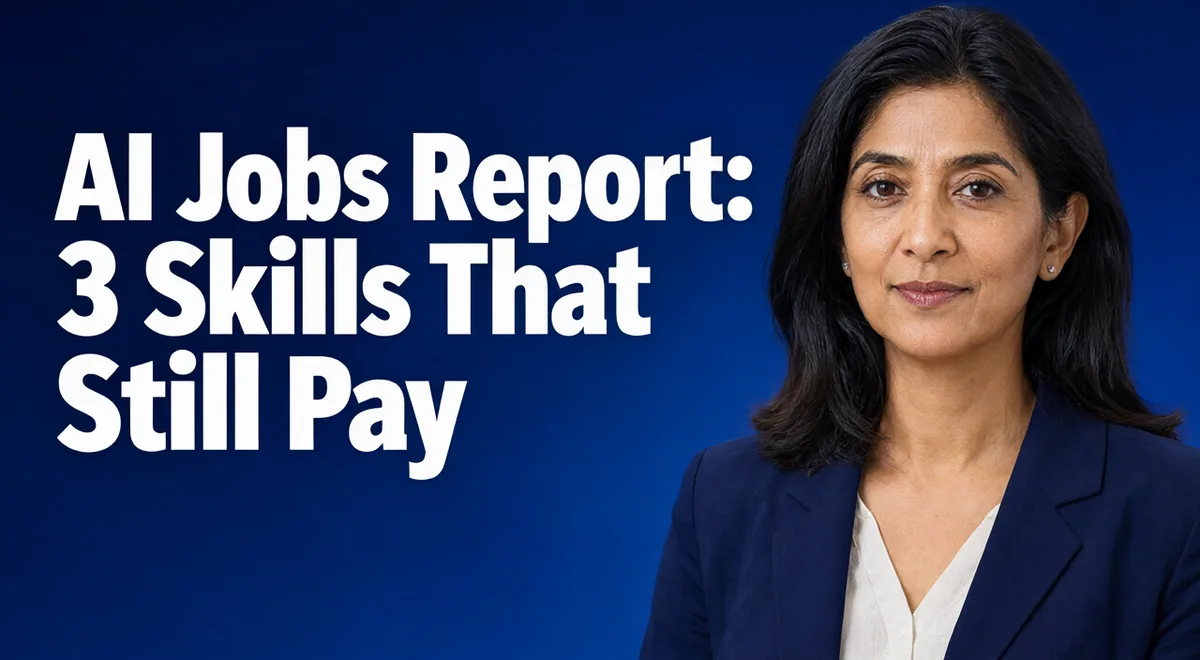
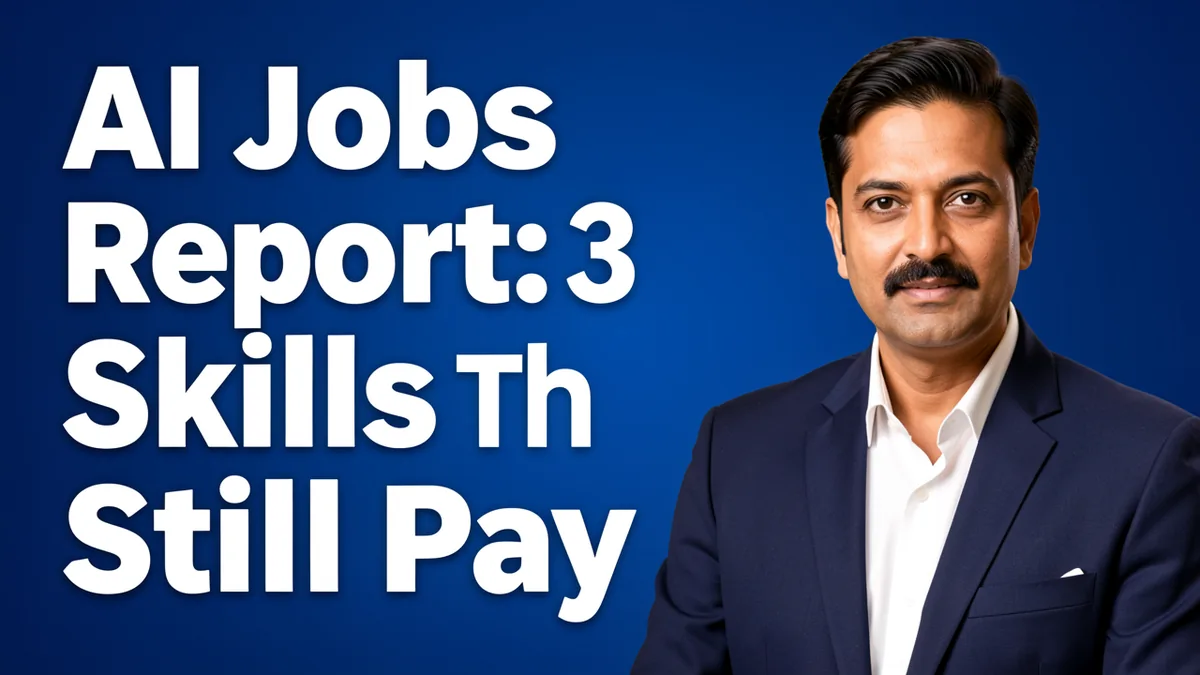
Prompt (s1a, seeds 101 & 202): “A YouTube-style news bulletin thumbnail. A bold white sans-serif headline reading exactly “AI Jobs Report: 3 Skills That Still Pay” fills the left two thirds in three stacked lines, with a confident Indian news presenter in a navy blazer on the right. Deep blue gradient background, high contrast, crisp clean typography, no other text.”
| Qwen-Image-2.1 | FLUX.2 Klein |
|---|---|
|
|
| Seed 101 — headline exact | Seed 101 — “3 SIkills” (inserted glyph) |
|
|
| Seed 202 — headline exact again | Seed 202 — “Skills Th” (“That” truncated) |
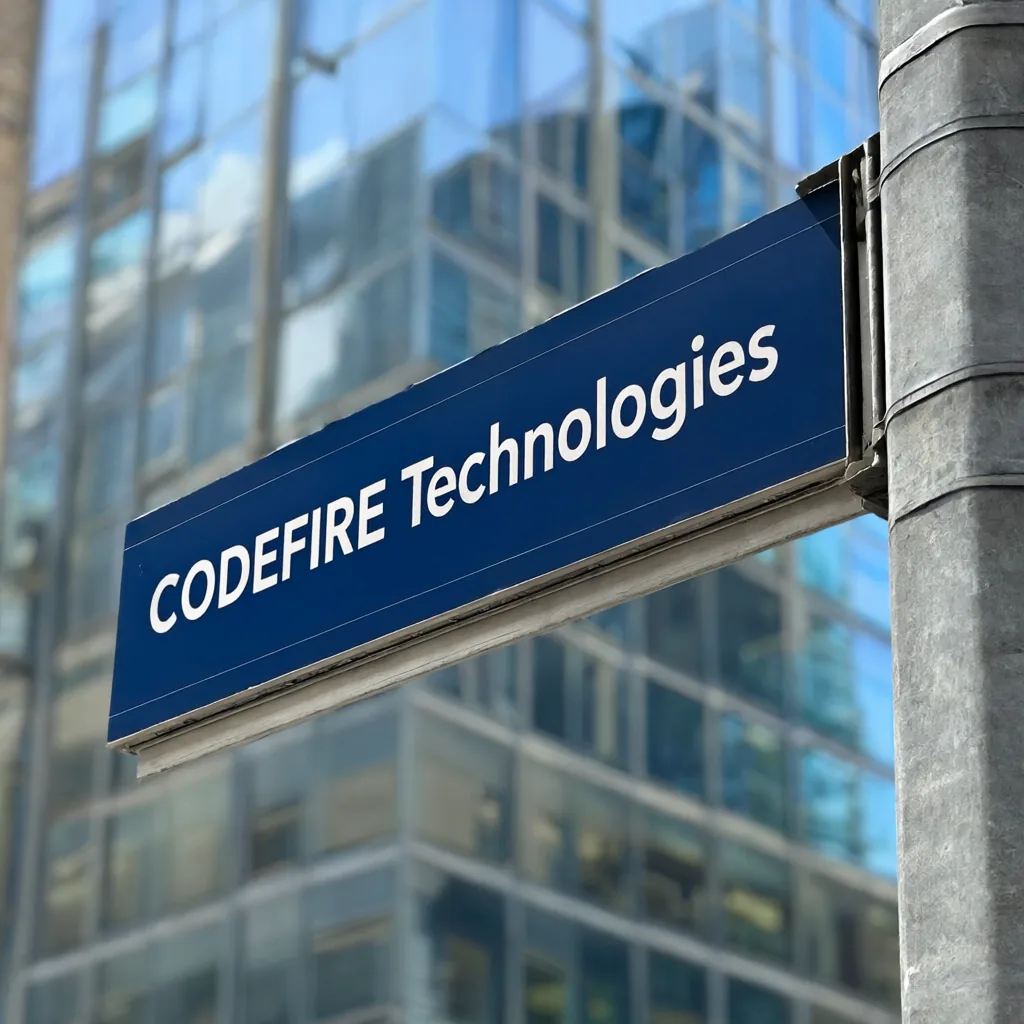
Prompt (s1b): “A photograph of a city street sign mounted on a metal pole. The sign reads exactly “CODEFIRE Technologies” in clean white capital letters on a dark blue background. Bright daylight, shallow depth of field, blurred glass office buildings behind, photorealistic.”
| Qwen | FLUX |
|---|---|
 |
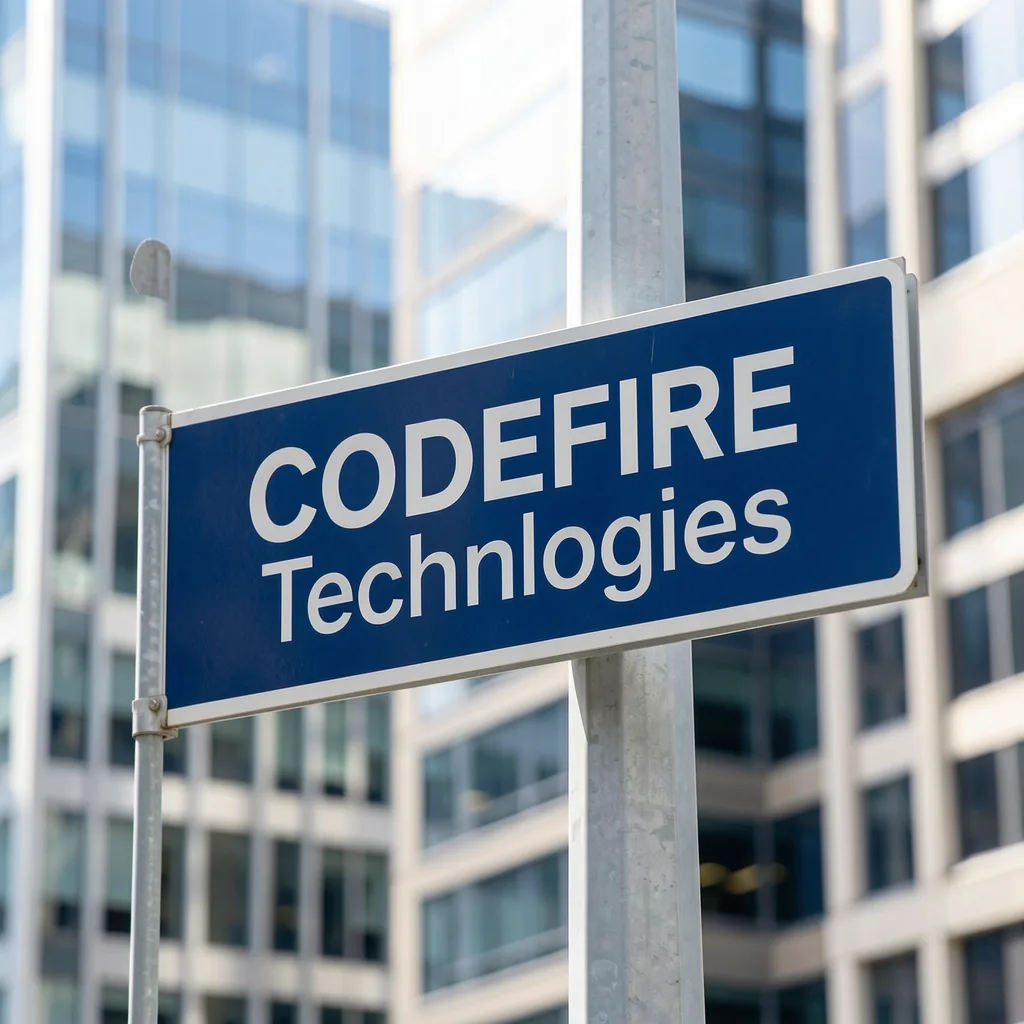 |
| “CODEFIRE Technologies” exact | “CODEFIRE Technlogies” — dropped the o |
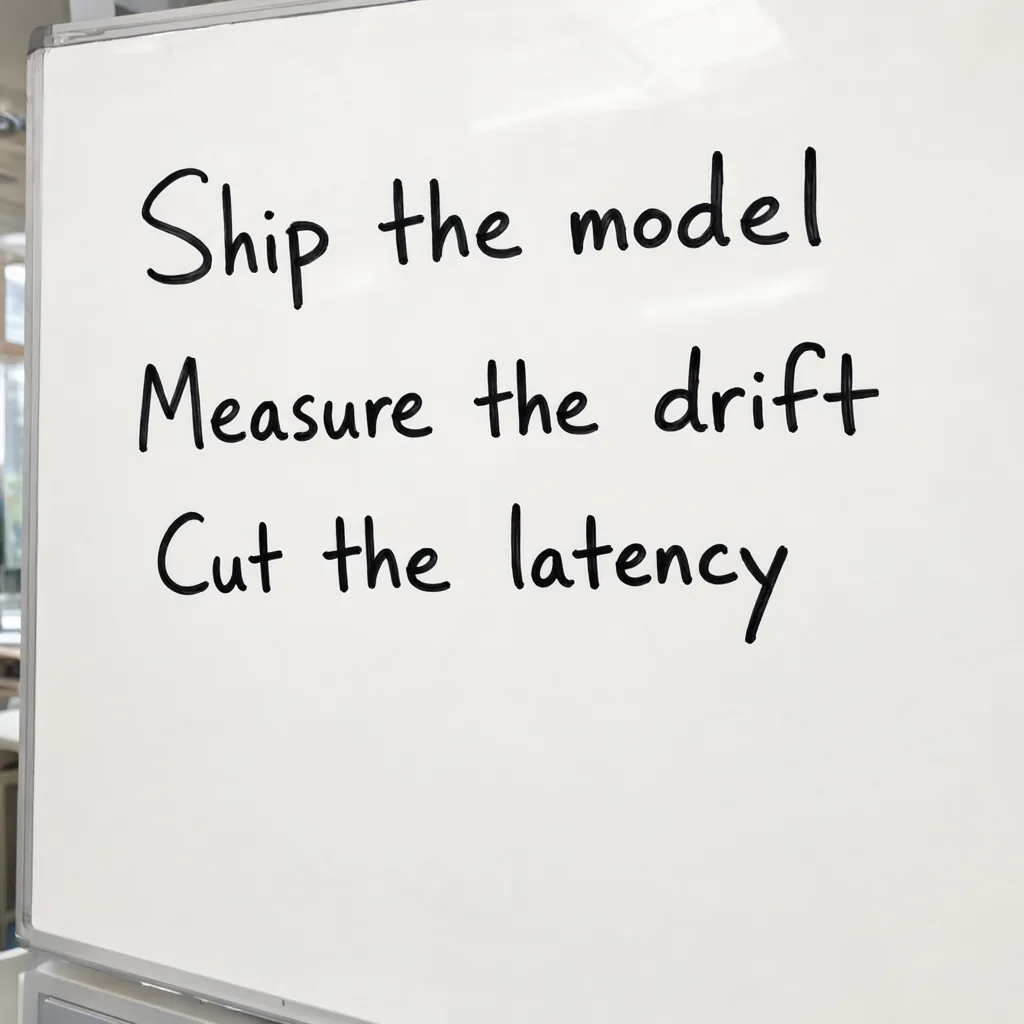
Prompt (s1c): “A close-up photograph of a white office whiteboard with exactly three short handwritten lines in black marker. The first line reads “Ship the model”. The second line reads “Measure the drift”. The third line reads “Cut the latency”. Neat handwriting, marker texture, bright office lighting, no other writing on the board.”
| Qwen | FLUX |
|---|---|
 |
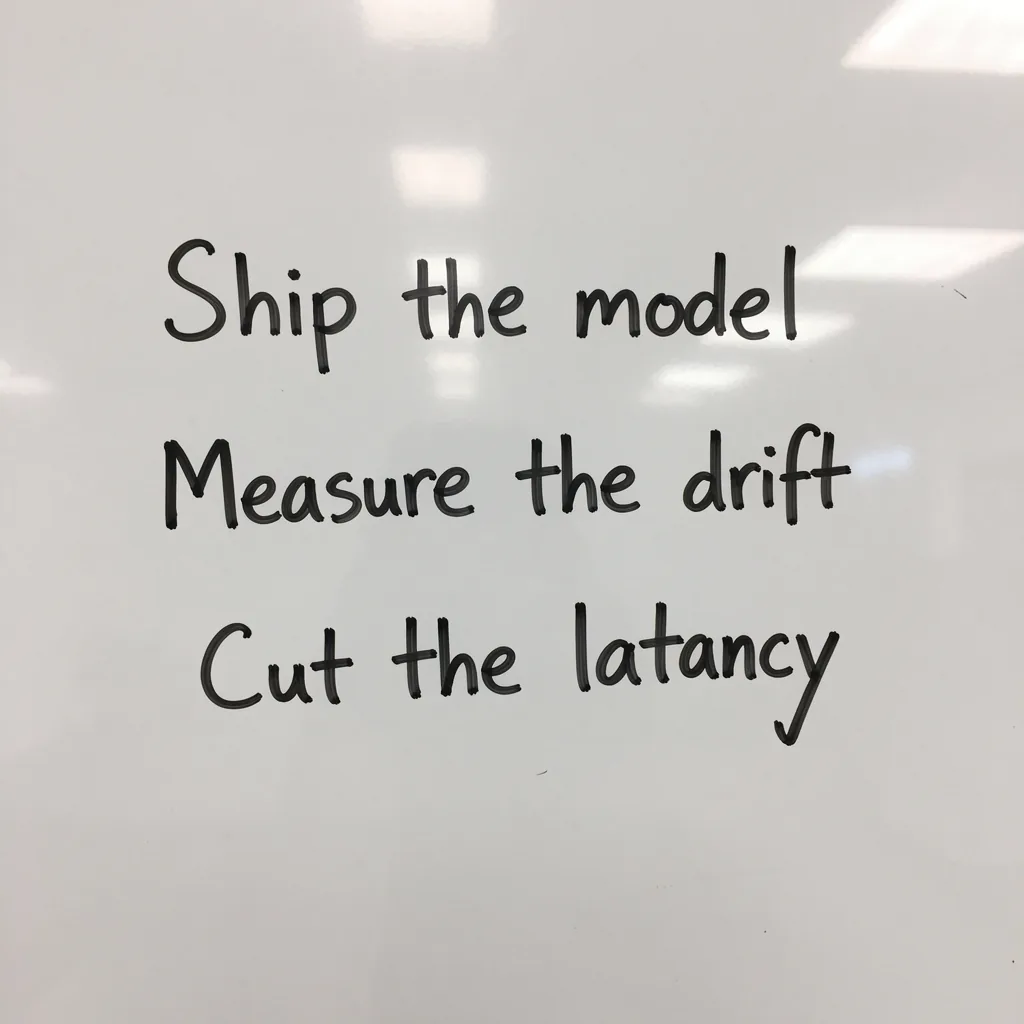 |
| All three lines exact | “Cut the latancy” — one wrong vowel |
Verdict: Qwen, decisively. Qwen 4/4 strings letter-perfect. FLUX 0/4 — every error a single
character in otherwise beautiful typography. 4.78 vs 4.06.
Slot 2 — Text rendering, Hindi (Devanagari)
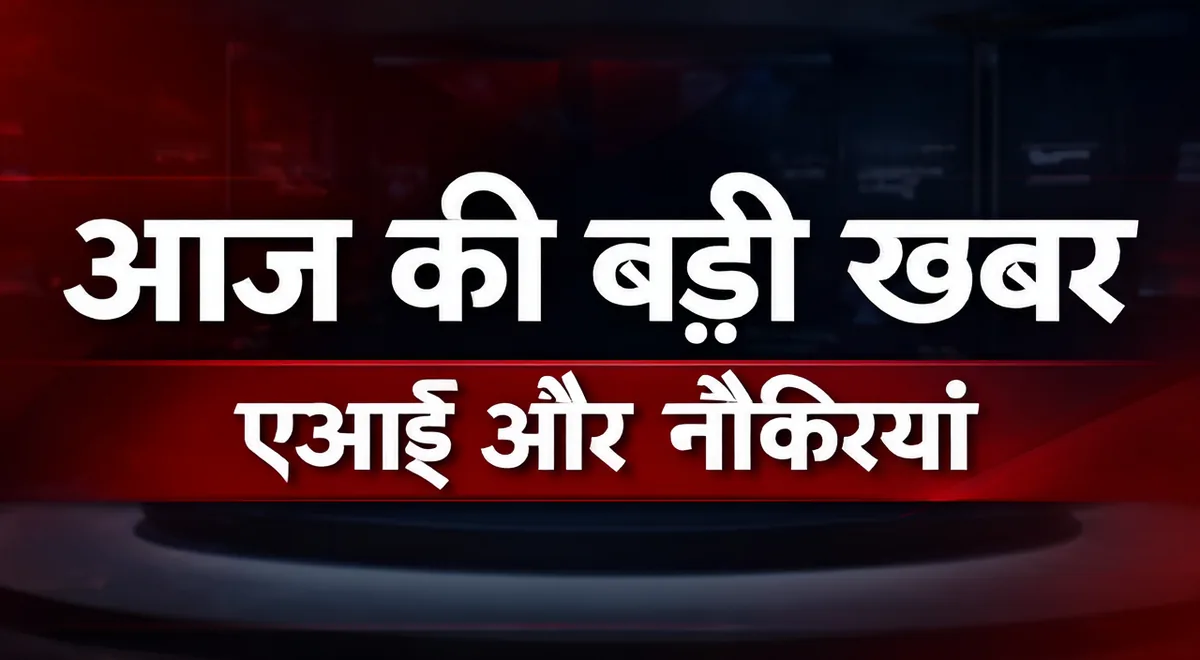
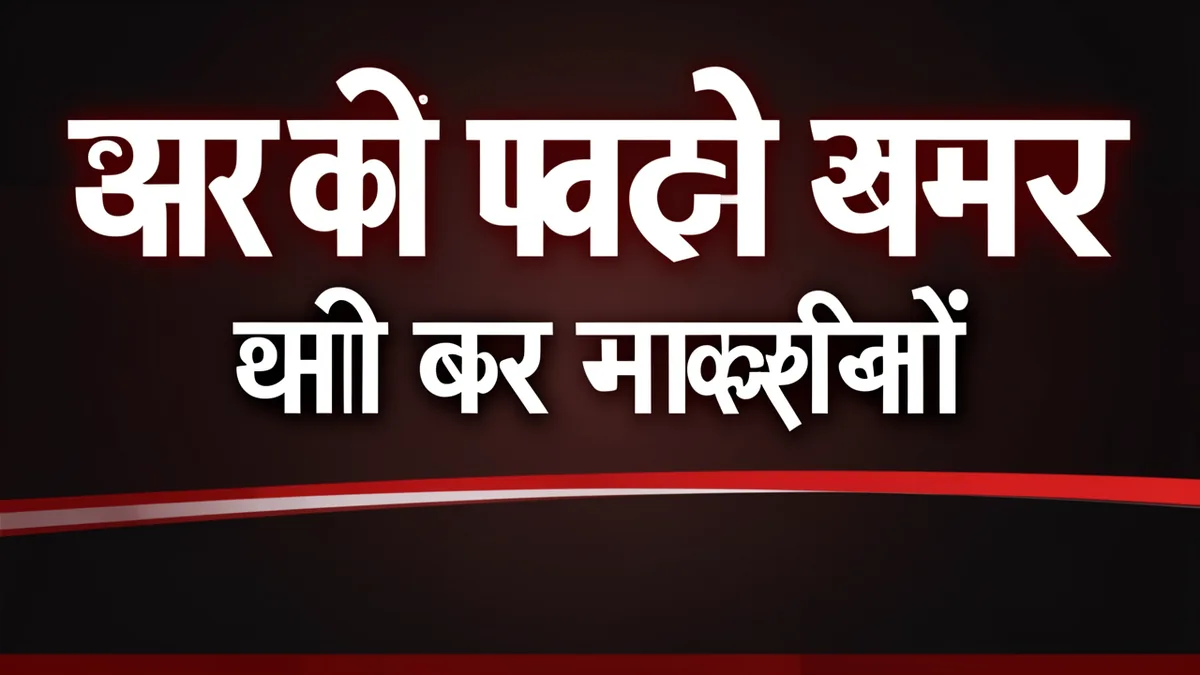
Prompt (s2a): “A Hindi television news poster. A large bold Devanagari headline across the top reads exactly “आज की बड़ी खबर”. Below it a smaller Devanagari subheading reads exactly “एआई और नौकरियां”. Deep red and white broadcast graphics, dark studio background, crisp correct Devanagari typography, no other text.”
| Qwen | FLUX |
|---|---|
|
|
| Both lines exact. 0/29 chars wrong | “अरको फवटे खमर / थाी कर माक्ख़ीबों” — ~30/30 wrong |
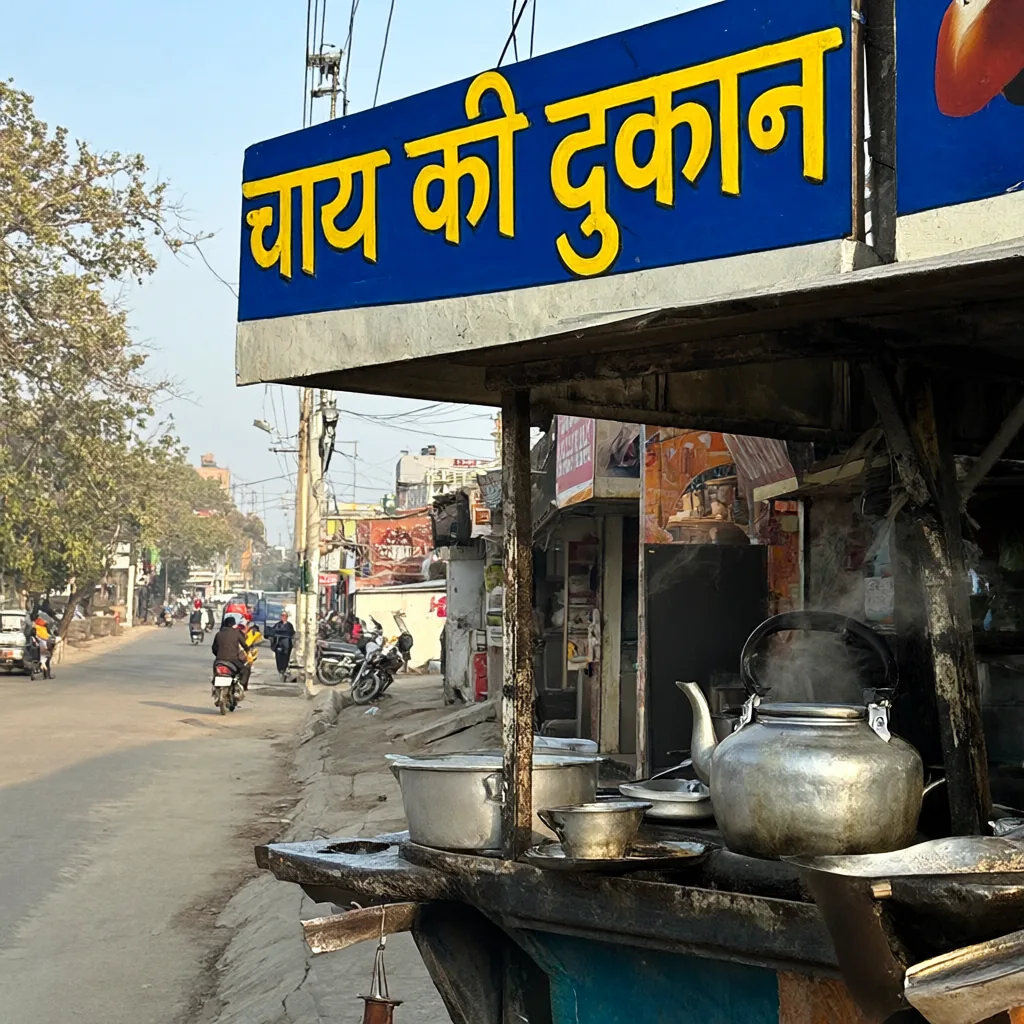
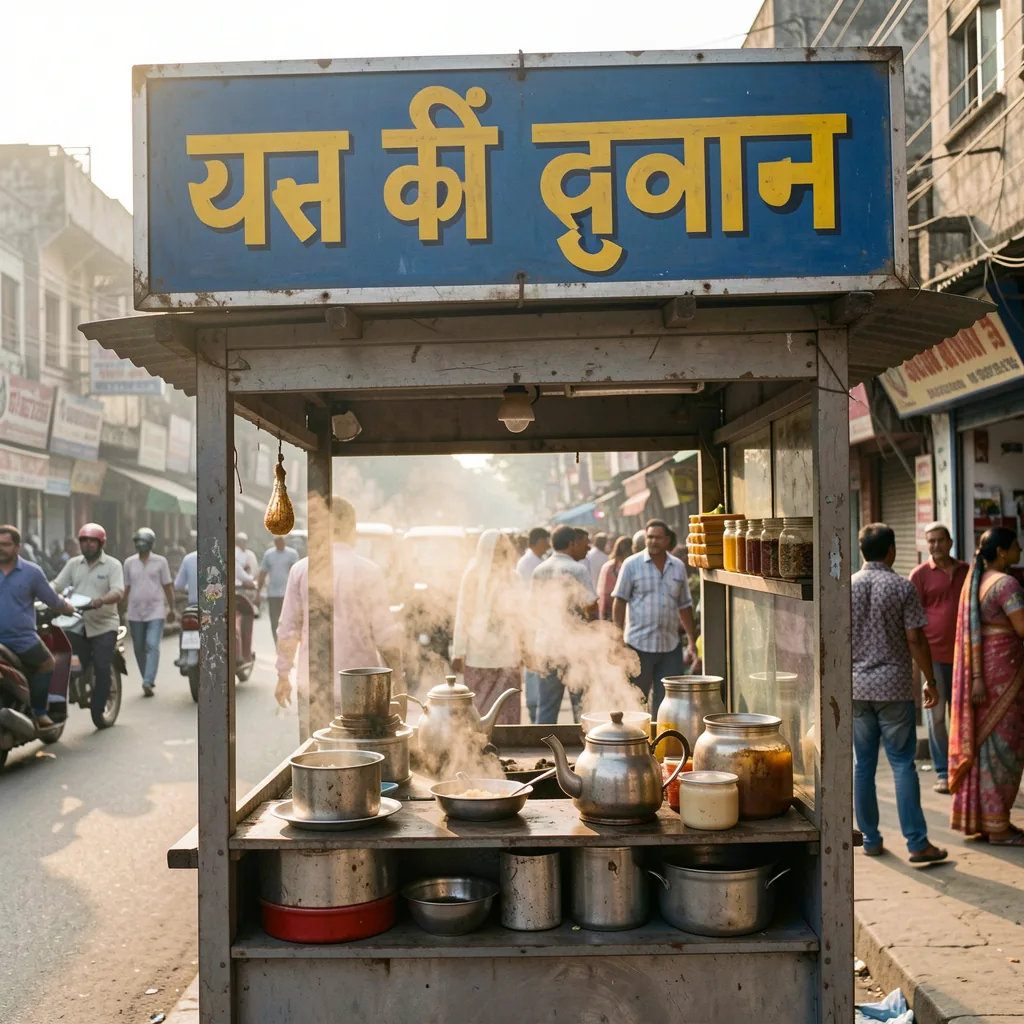
Prompt (s2b): “A photograph of a small Indian roadside tea stall. A painted signboard above the stall reads exactly “चाय की दुकान” in bold yellow Devanagari letters on a blue background. Morning light, steam rising from a kettle, busy street behind, photorealistic, no other text.”
| Qwen | FLUX |
|---|---|
|
|
| “चाय की दुकान” exact | “यत्त कीं द्वनान” — 12/12 chars wrong |
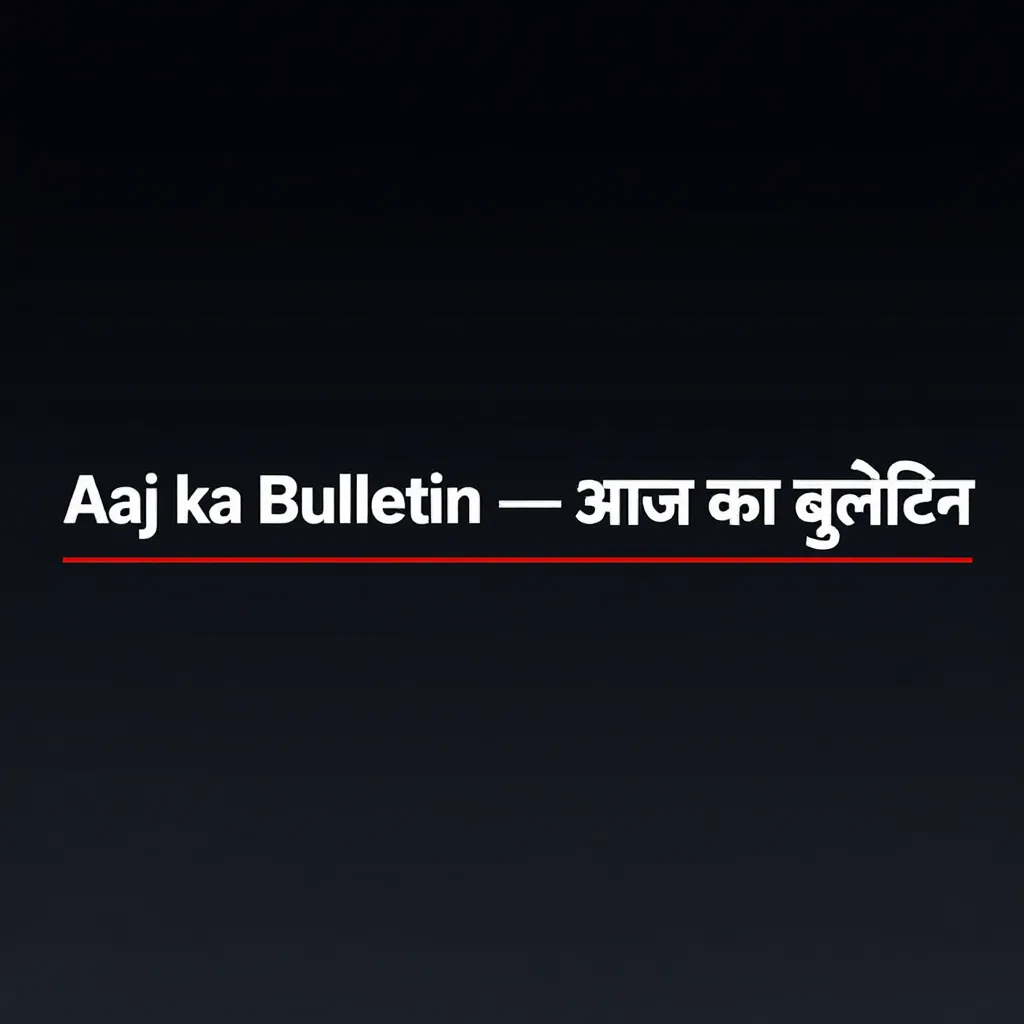
Prompt (s2c): “A modern television lower-third graphic on a dark background showing exactly one line of mixed Latin and Devanagari text reading “Aaj ka Bulletin — आज का बुलेटिन”, clean white type with a thin red underline beneath it, broadcast quality, no other text.”
| Qwen | FLUX |
|---|---|
 |
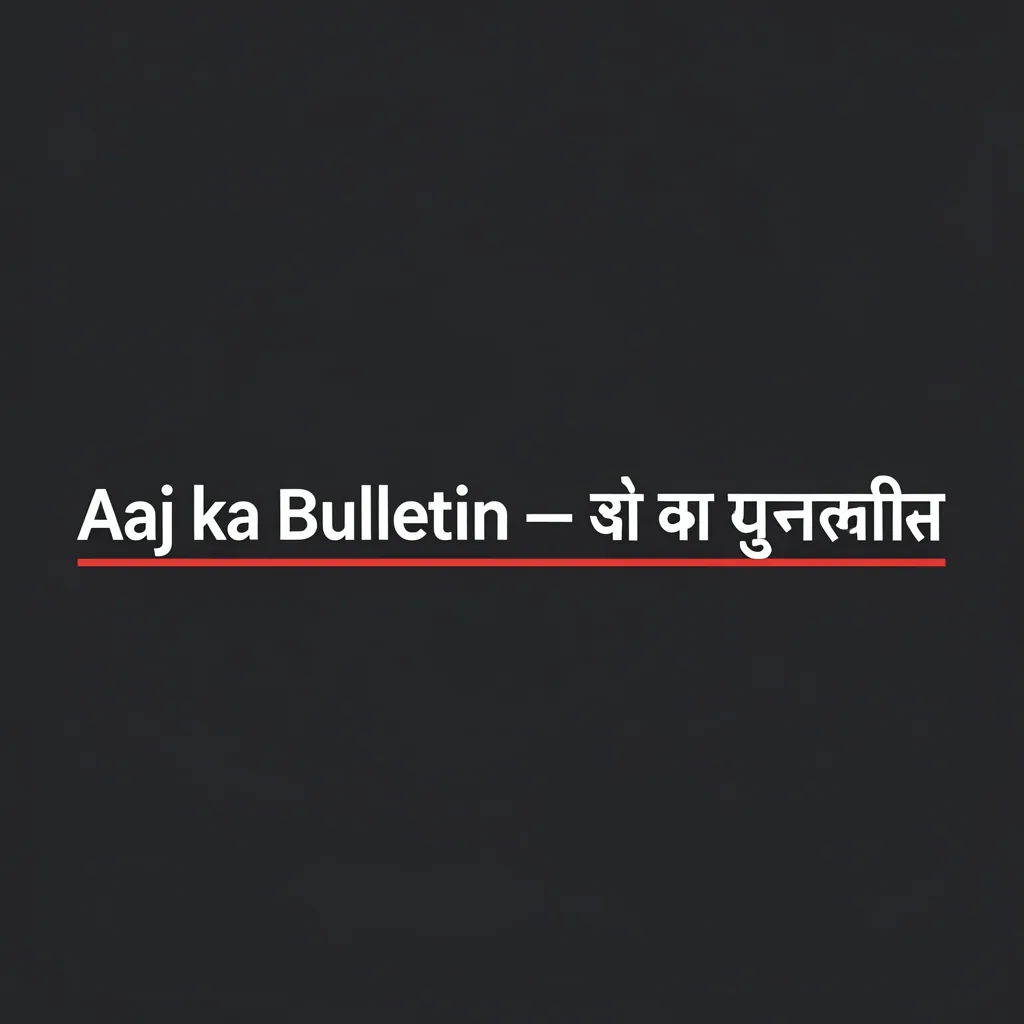 |
| Exact, both scripts, correct em dash | Latin half perfect, Devanagari half gibberish |
Verdict: Qwen, and it is not close. Qwen rendered every string exactly — correct nuqta on ड़,
correct ि attaching to र (not क), correct shirorekha and conjuncts. Roughly 55/55 characters correct versus
~55/55 wrong for FLUX. FLUX’s Latin half of the mixed line was perfect, so the failure is specifically
Devanagari. This reproduces an earlier single-poster finding at 3× the sample size. 4.83 vs
3.33.
Slot 3 — Humans, portrait
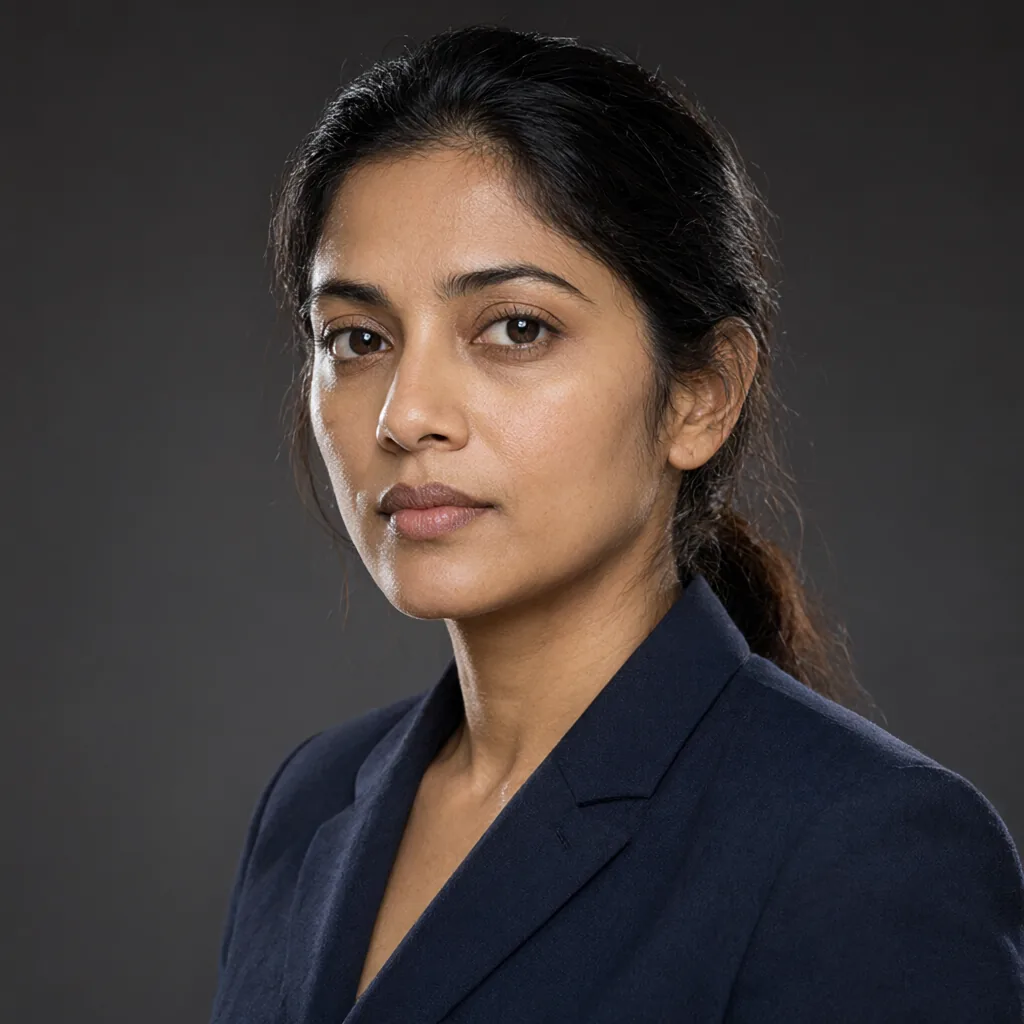
Prompt (s3a): “Studio portrait photograph of a 32-year-old Indian woman news presenter, three-quarter view turned slightly to her left, natural untouched skin texture with visible pores and fine lines, dark hair tied back, navy blazer, soft key light with a subtle rim light, neutral dark grey backdrop, 85mm lens, photorealistic, no text.”
| Qwen | FLUX |
|---|---|
 |
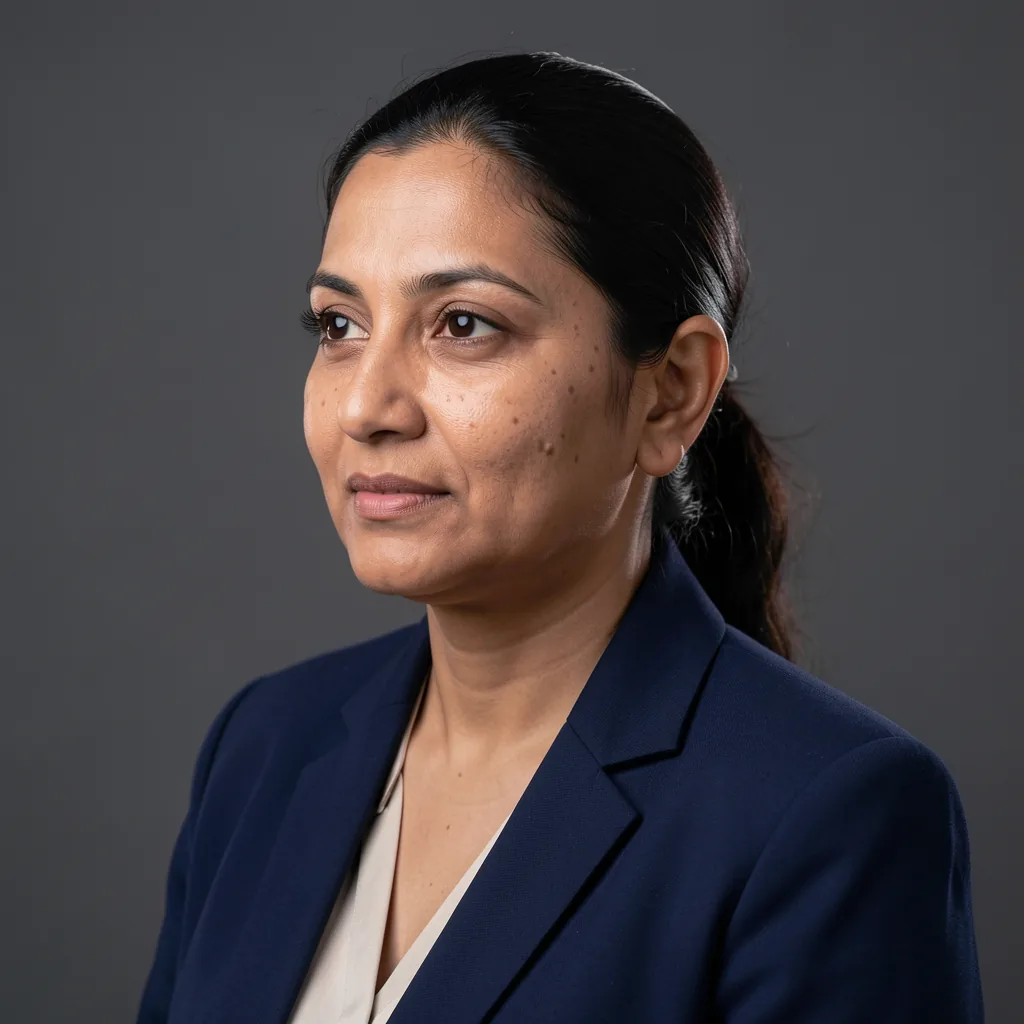 |
| Near-frontal (not ¾), skin smoothed | True ¾ view, real pores/moles — best skin in test |
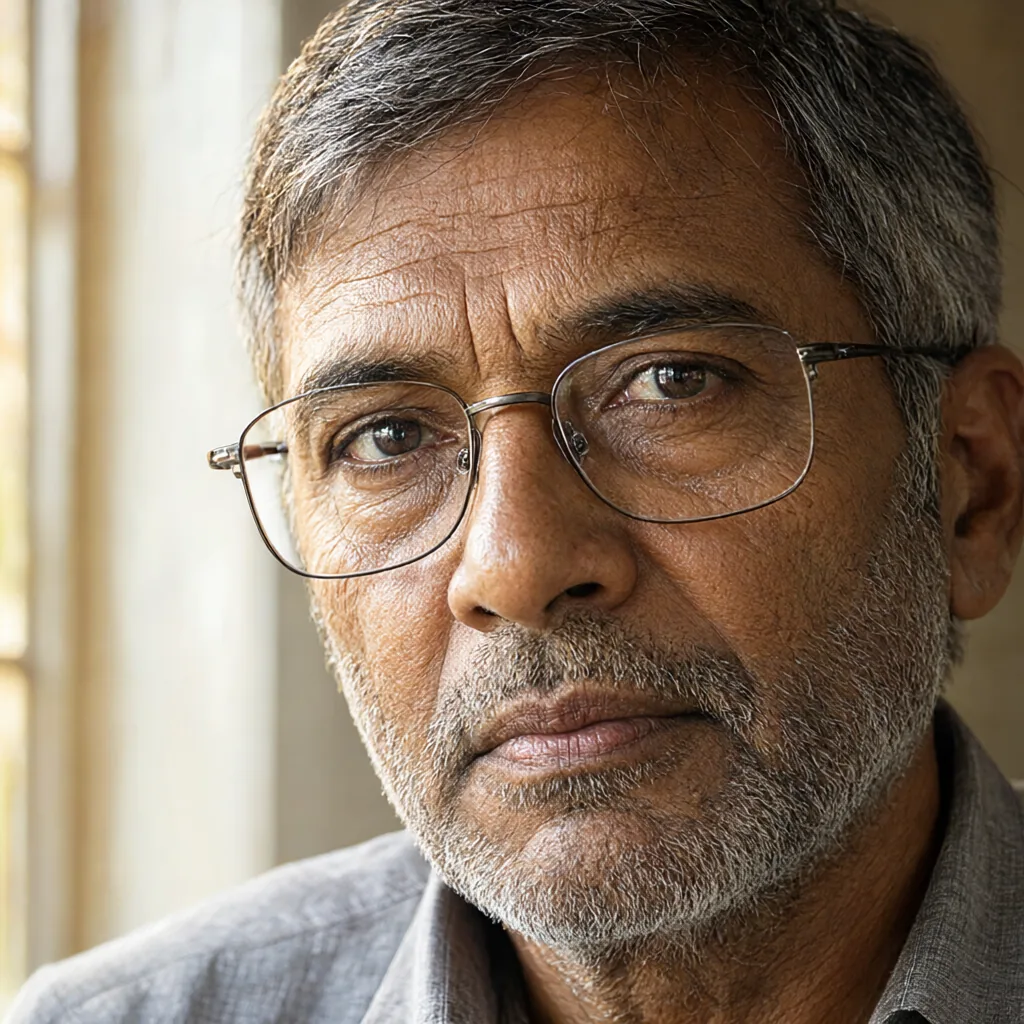
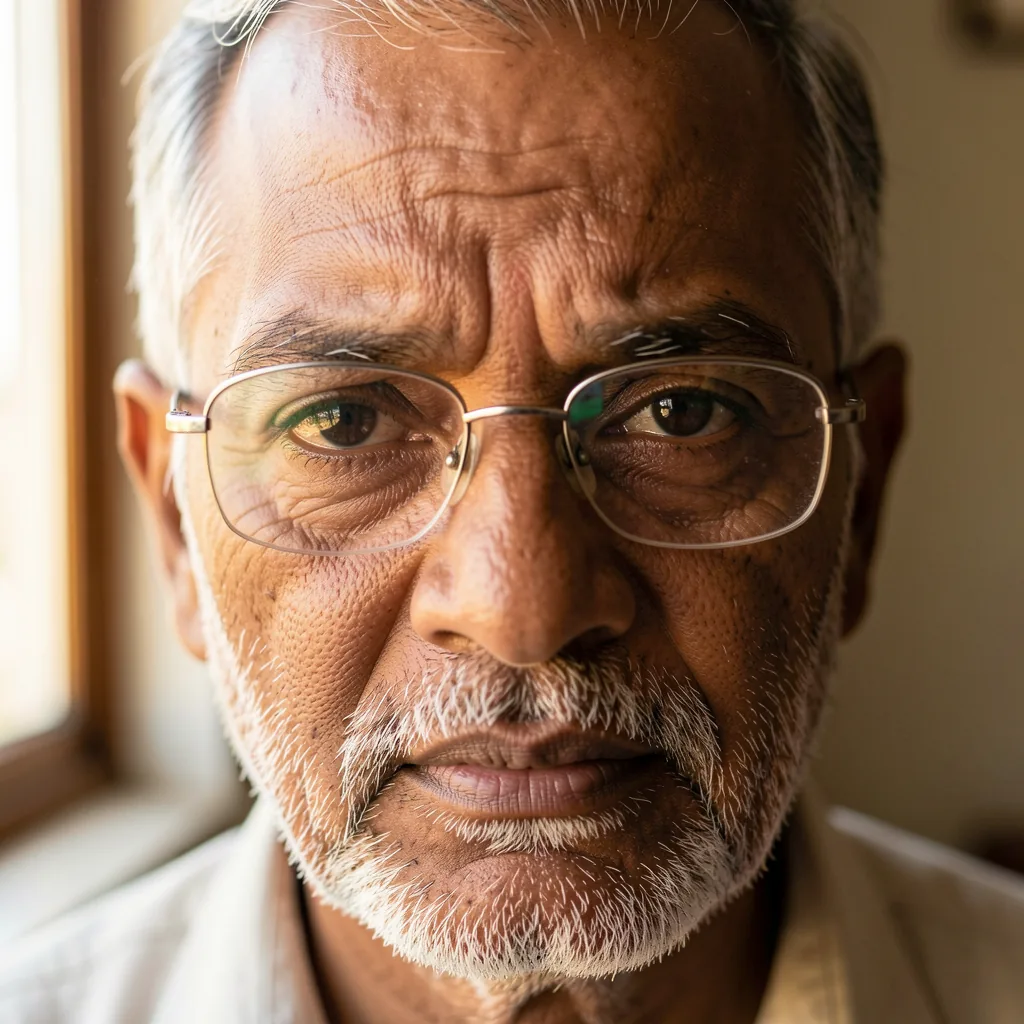
Prompt (s3b): “Close-up photographic portrait of a 60-year-old Indian man, deep forehead and eye wrinkles, salt-and-pepper stubble, wire-rimmed glasses, warm window light from the left, sharp catchlights in the eyes, shallow depth of field, photorealistic, no text.”
| Qwen | FLUX |
|---|---|
|
|
| Reads ~50, moderate lines | Convincing 60+, deep wrinkles |
Verdict: FLUX. It hit the requested three-quarter view and produced the best skin texture in the
entire test — visible pores, moles, asymmetry. Qwen smoothed. Both models undershot the ages (Qwen ~38/50,
FLUX ~45/60+) — if you need a specific age, state a decade and check, on either model. 4.38 vs
4.62.
Slot 4 — Humans, full body & pose
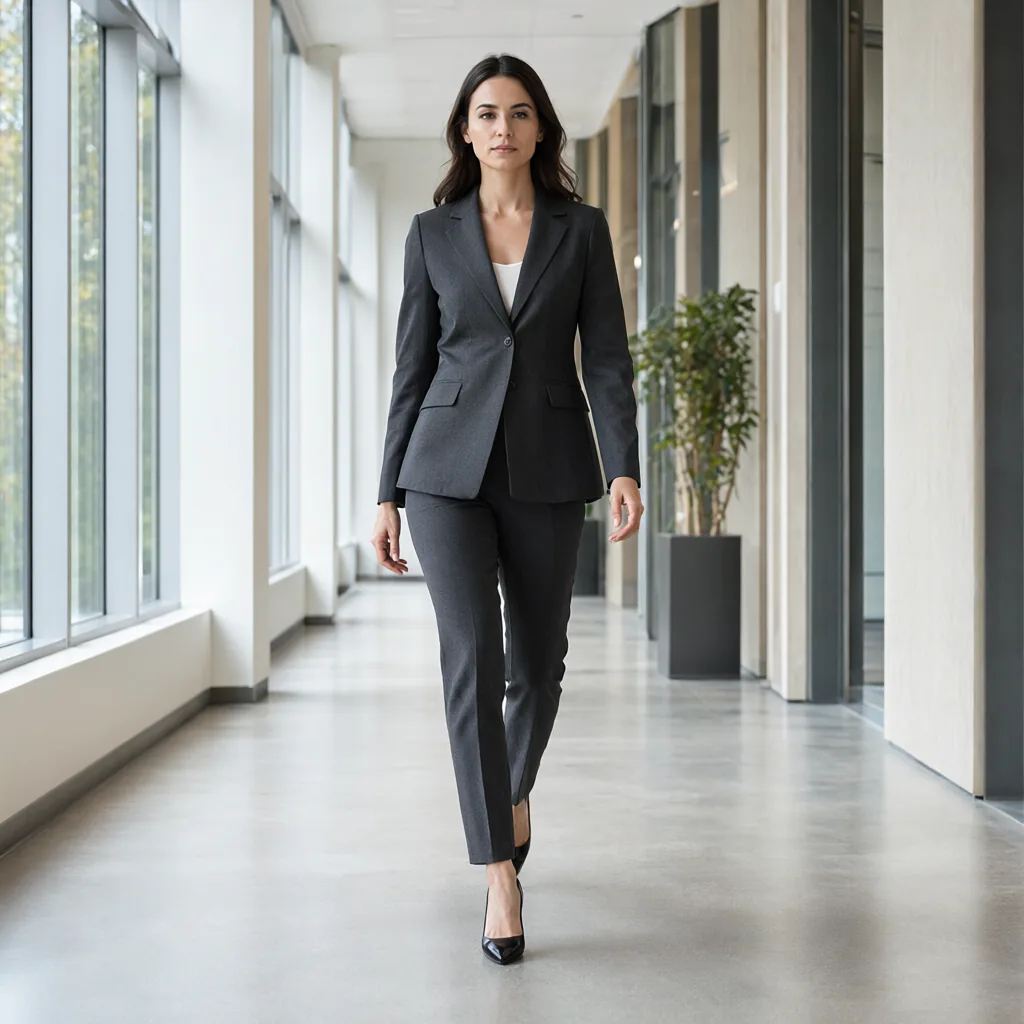
Prompt (s4a): “Full-body photograph of a woman in a charcoal blazer and trousers walking down a modern office corridor towards the camera, mid-stride, both feet and both hands fully visible, natural daylight from windows on the left, photorealistic, sharp, no text.”
| Qwen | FLUX |
|---|---|
 |
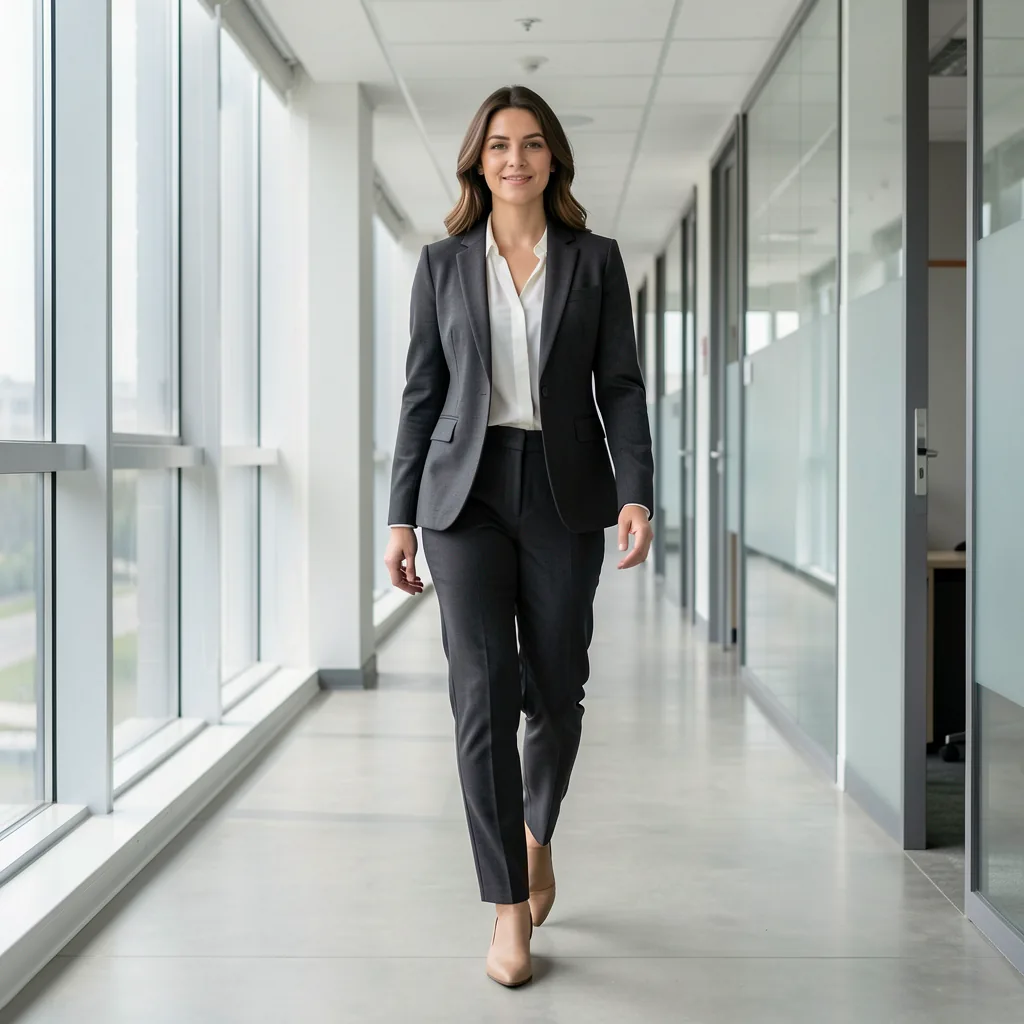 |
| Genuine mid-stride, both hands & feet in frame | Equally Good |
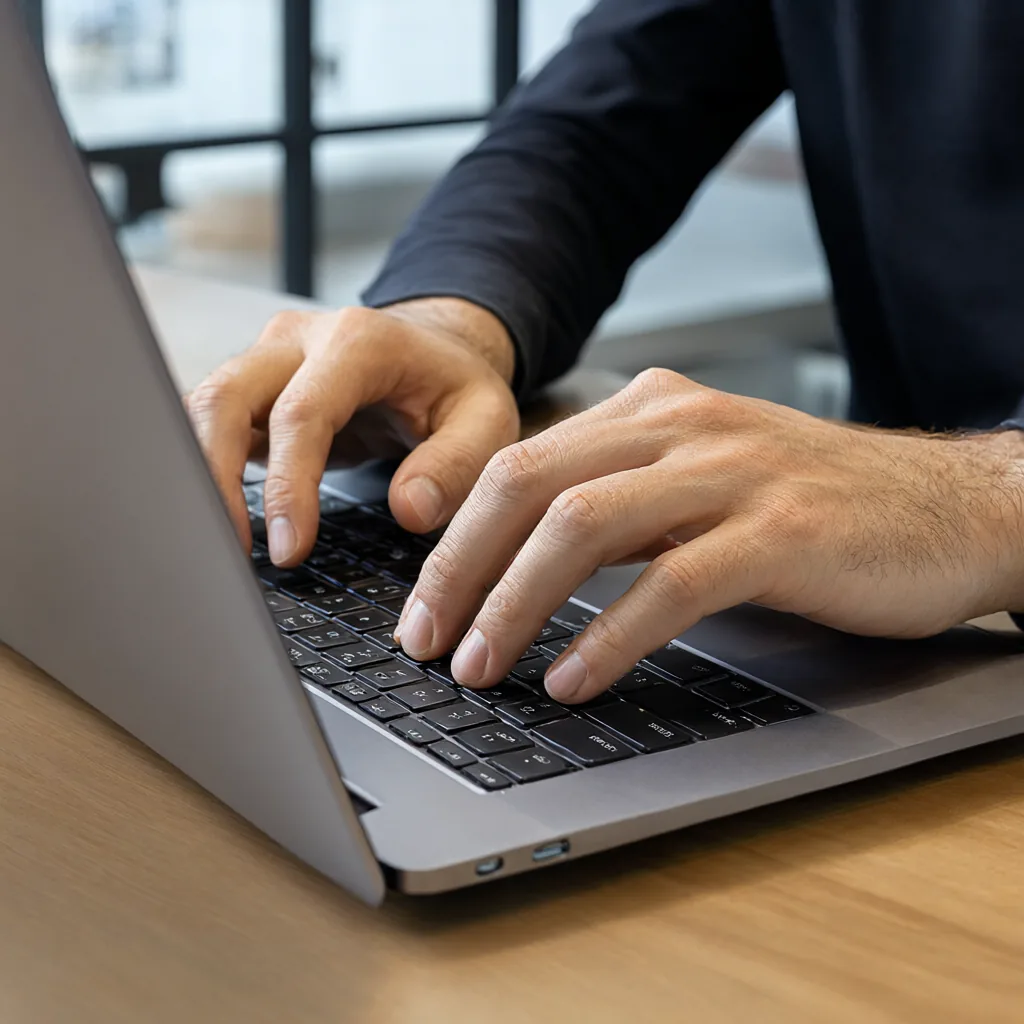
Prompt (s4b): “Photograph of a man sitting at a wooden desk typing on a laptop keyboard, both hands clearly visible resting on the keys with all fingers in frame, side-lit modern office, sharp focus on the hands, photorealistic, no text.”
| Qwen | FLUX |
|---|---|
 |
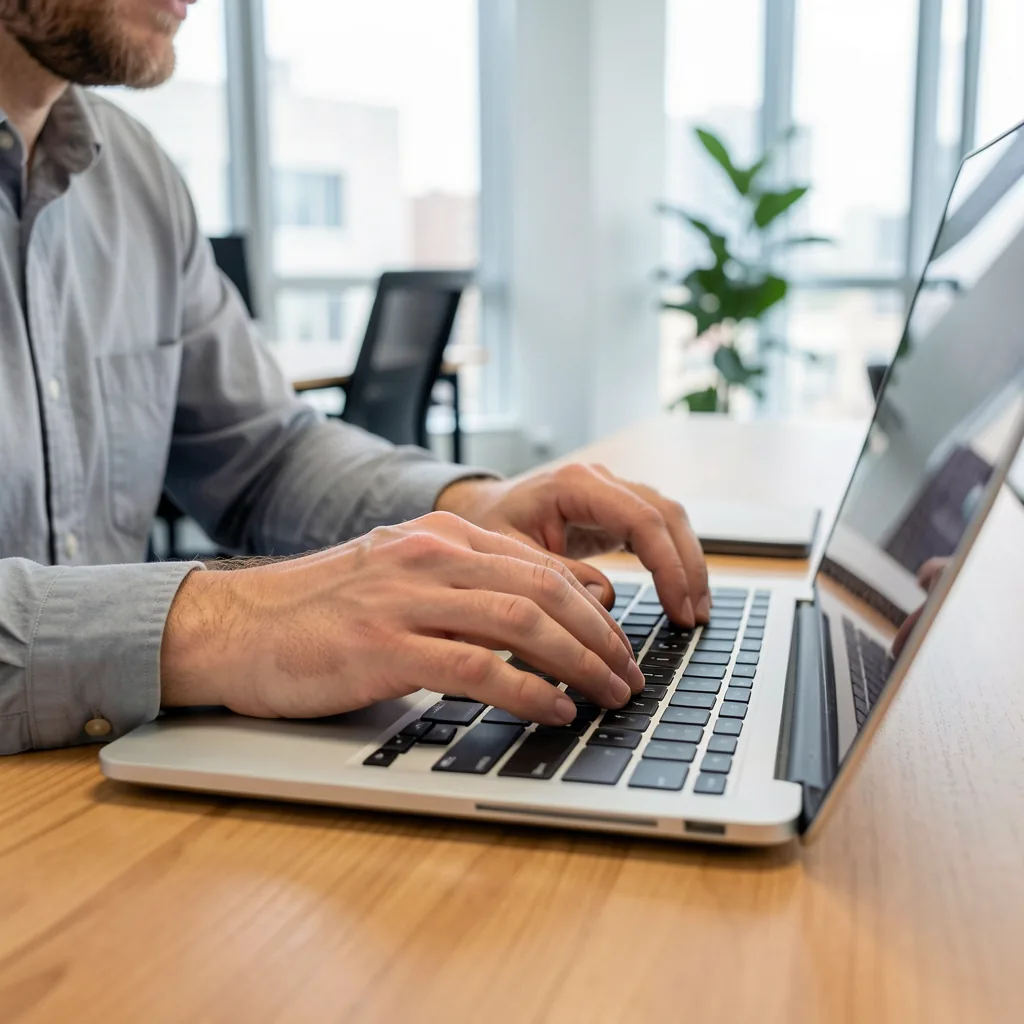 |
| Man absent — cropped to hands + sleeve | Man, desk, both hands — as asked |
Verdict: effectively a tie, given to FLUX. Qwen framed the walk better but catastrophically
mis-framed the typing shot, cropping to hands and a sleeve and omitting the man entirely despite “a man sitting at a
desk” leading the prompt. Qwen’s hands were the cleanest in the test (correct fingers, nails, no fusion); FLUX
composed correctly but merged fingers slightly. Neither produced a finger-count failure. 4.25 vs
4.12.
Slot 5 — Humans, groups & diversity
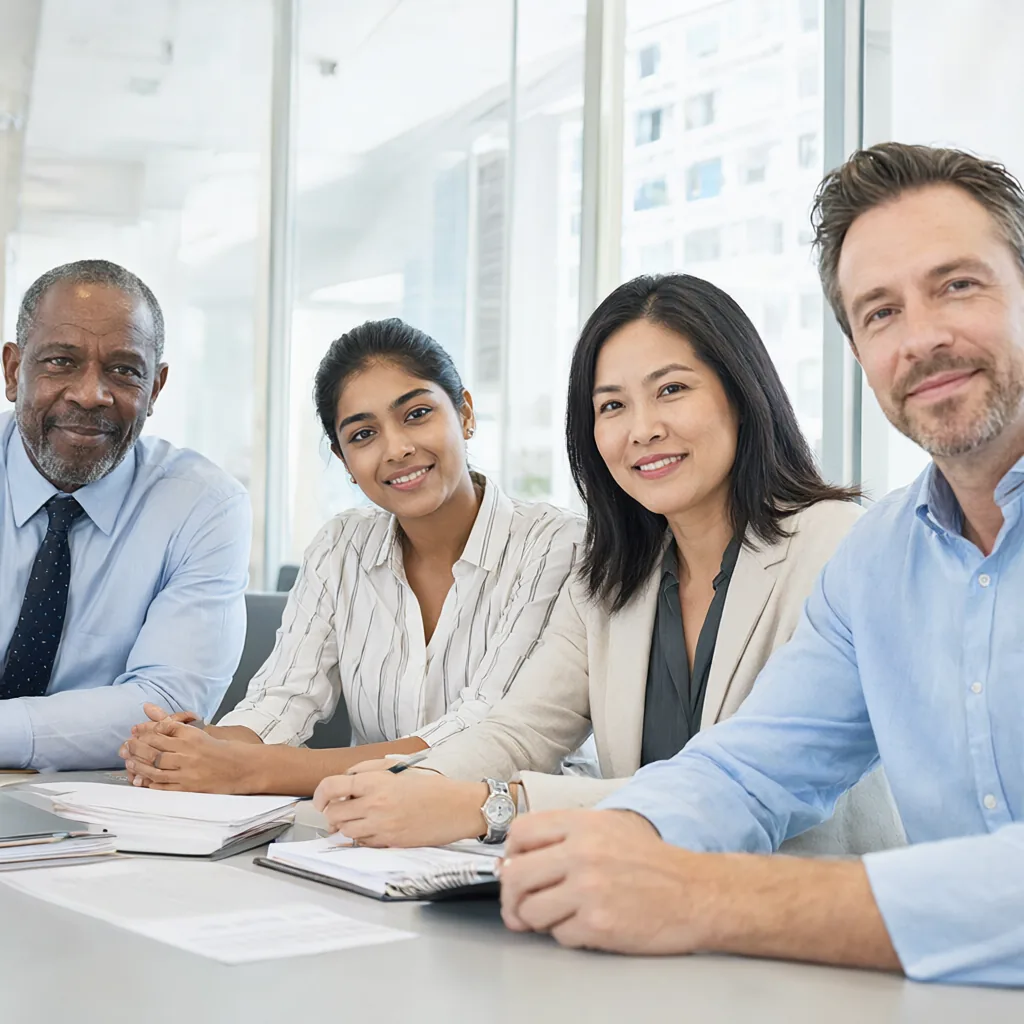
Prompt (s5a): “Photograph of four colleagues of different ages and skin tones seated around a meeting table, all four faces fully visible and turned towards the camera: an older Black man, a young South Asian woman, a middle-aged East Asian woman, and a white man in his forties. Bright modern office, photorealistic group shot, no text.”
| Qwen | FLUX |
|---|---|
 |
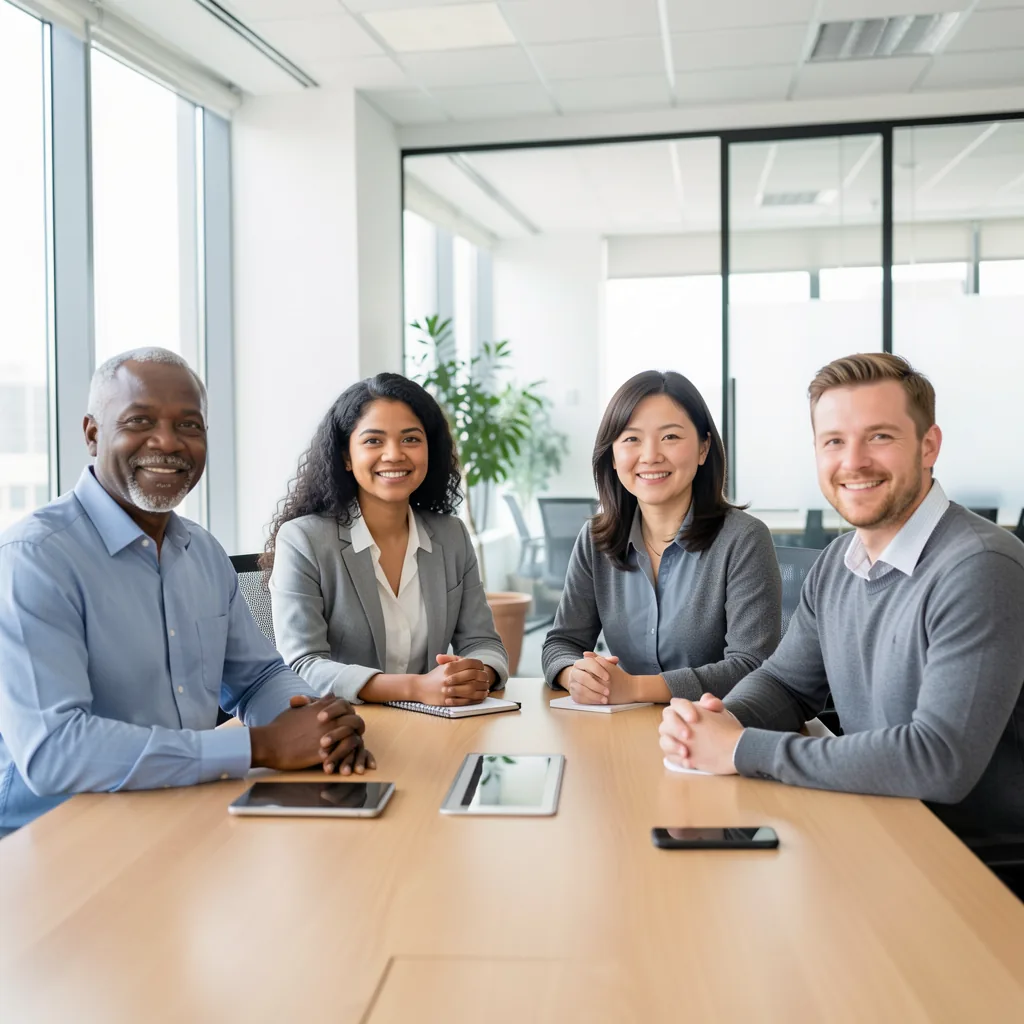 |
| All four demographics correct | Same four, cleaner hands, wider room |
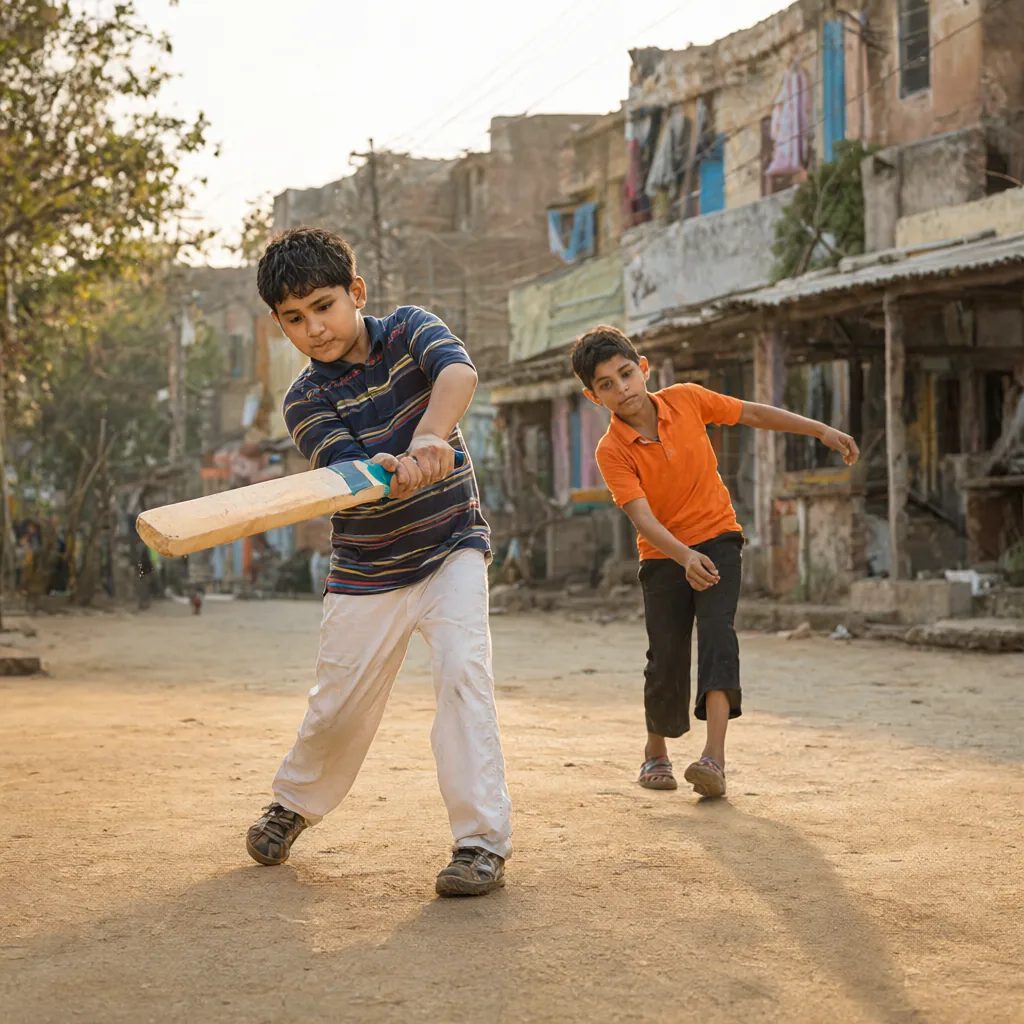
Prompt (s5b): “Photograph of two children playing cricket on a dusty Indian street, one batting with the bat raised and one bowling with the arm in motion, warm late afternoon light, photorealistic, no text.”
| Qwen | FLUX |
|---|---|
 |
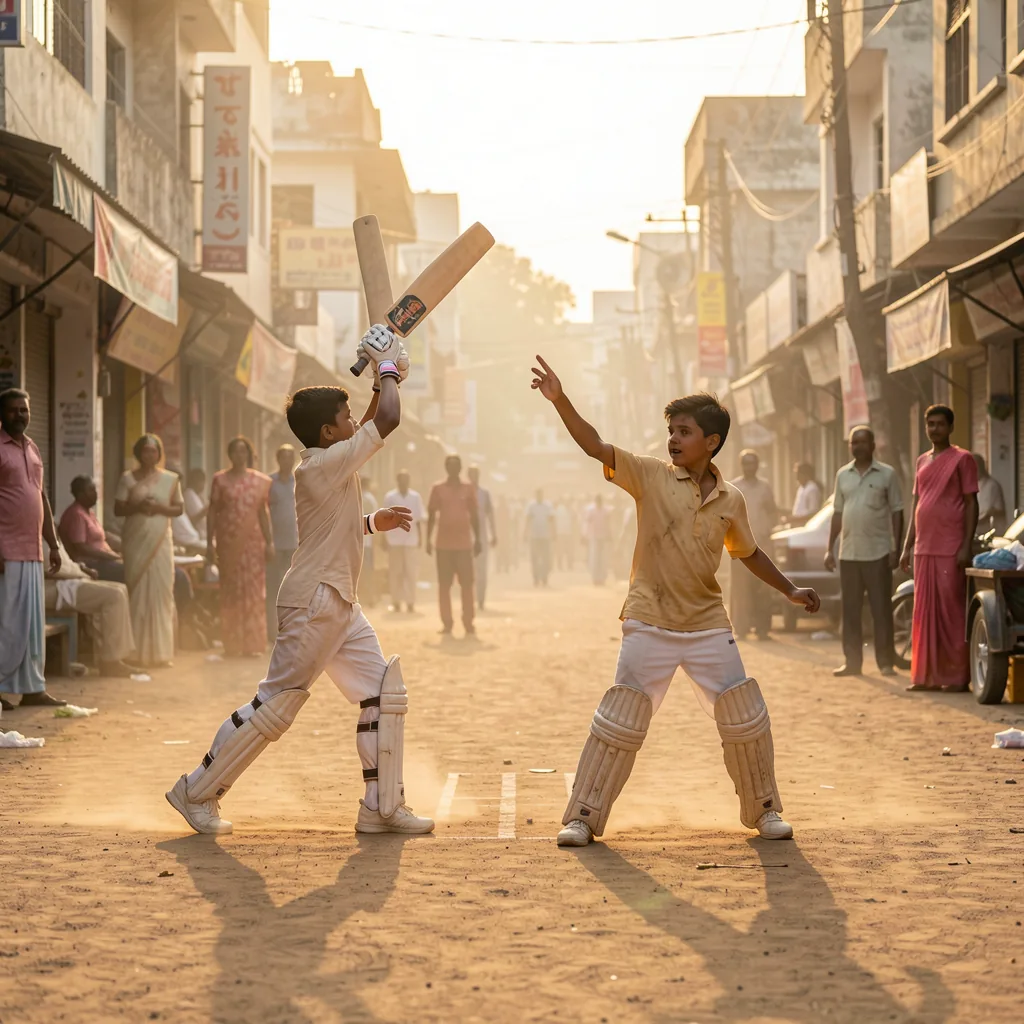 |
| Real street cricket, batting stroke | Staged, padded kids; garbled signage |
Verdict: Qwen, narrowly. Both nailed the four demographics with all faces to camera. Qwen’s cricket
is real street cricket; FLUX’s is two padded-up kids posing, with garbled shop signage across the background — the
Devanagari weakness leaking into a non-text prompt. 4.38 vs 4.12.
Slot 6 — Humans, action & expression
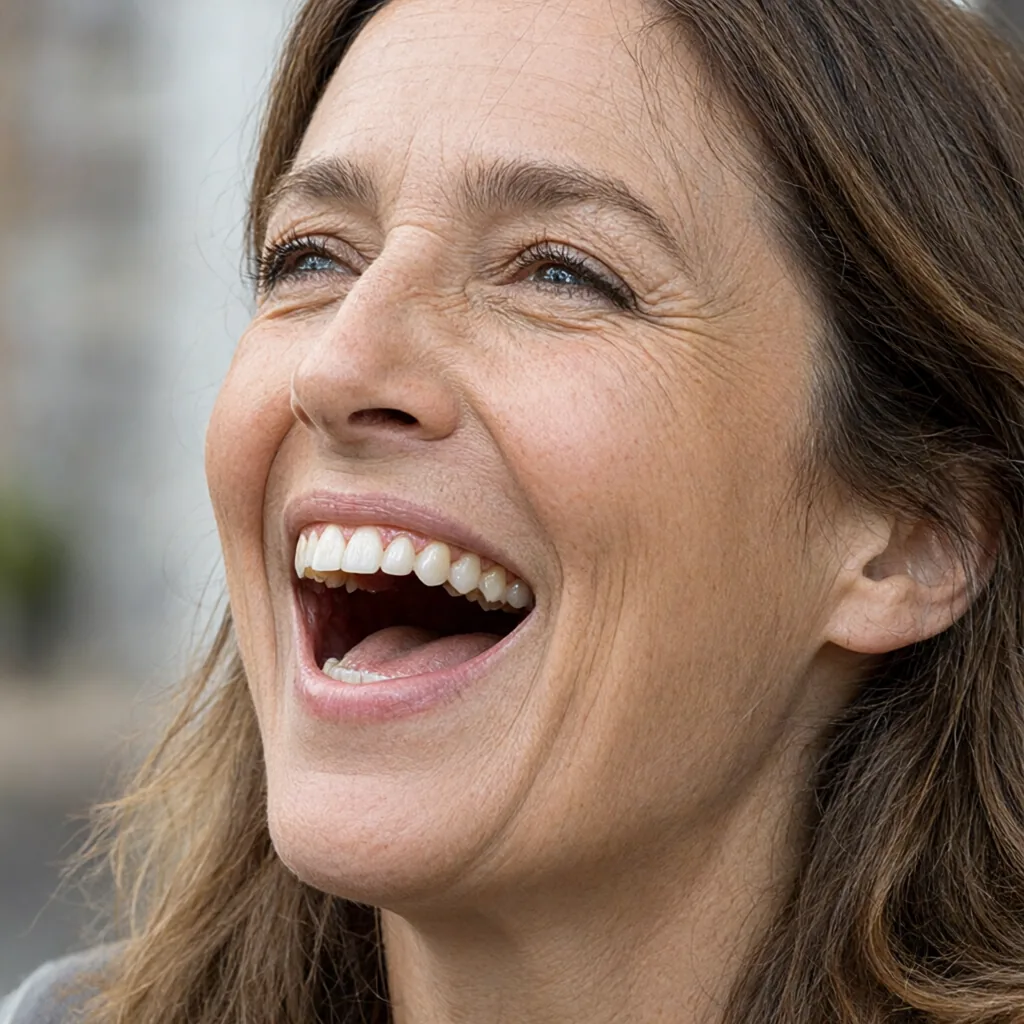
Prompt (s6a): “Close-up photograph of a woman laughing mid-sentence, mouth open wide, upper teeth clearly visible, eyes crinkled, head tilted back slightly, candid and natural, soft daylight, photorealistic, sharp detail, no text.”
| Qwen | FLUX |
|---|---|
 |
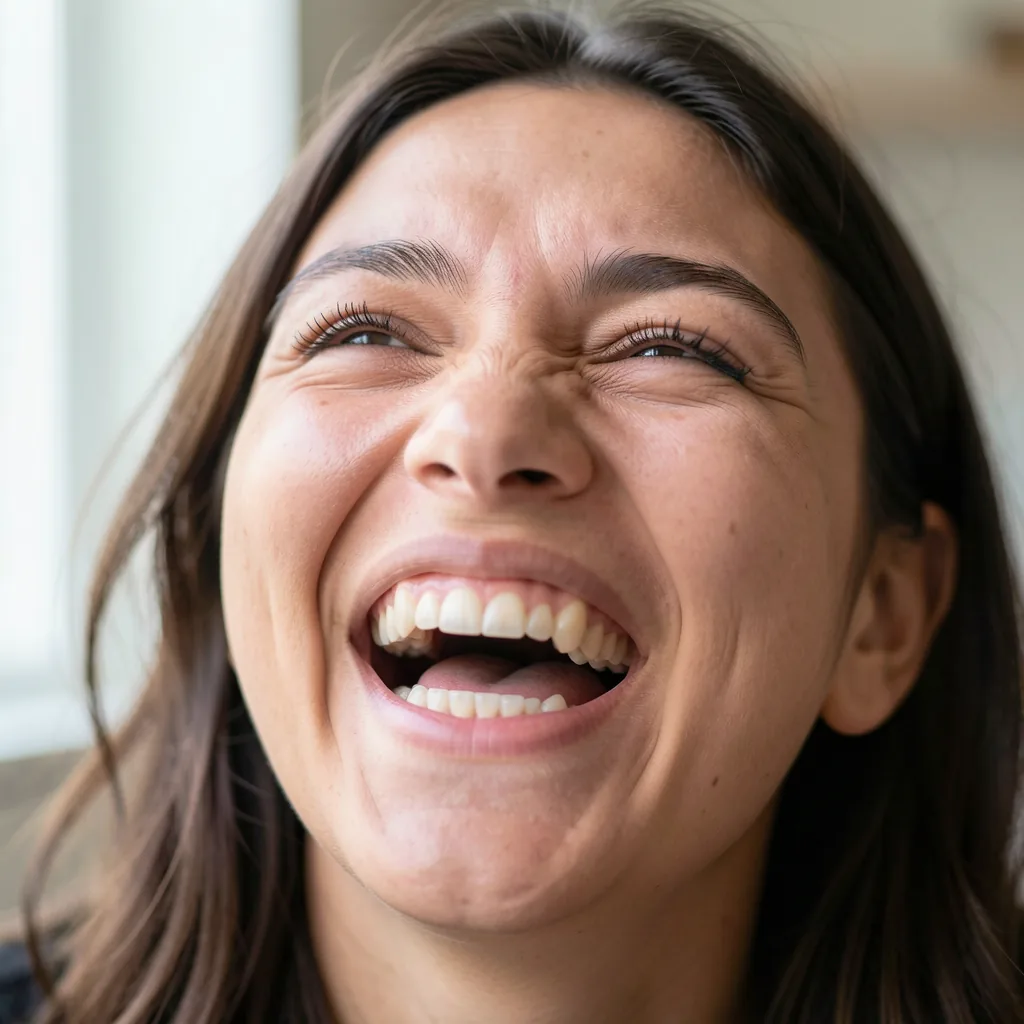 |
| Real teeth, real crow’s feet — dead tie | Equally excellent |
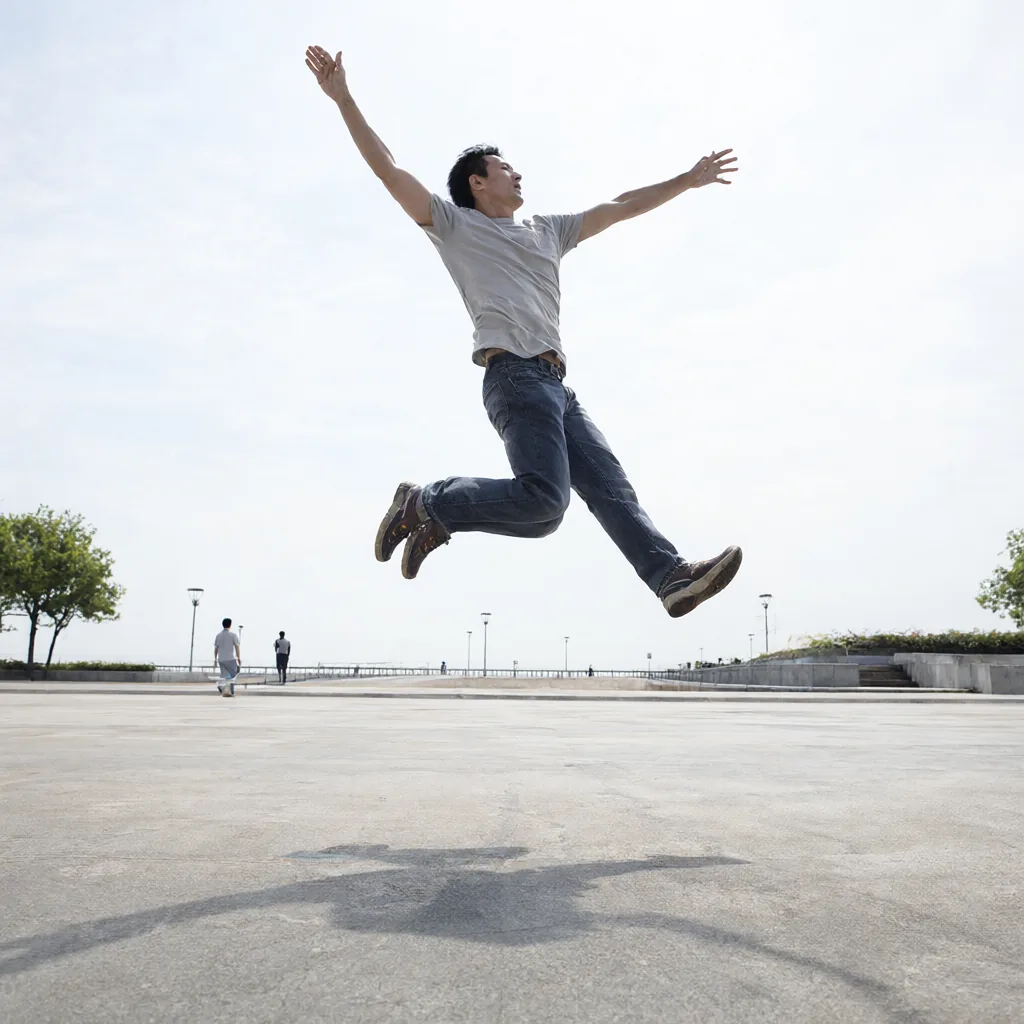
Prompt (s6b): “Photograph of a man mid-jump in the air above a concrete plaza, arms and legs fully extended, entire body in frame, low camera angle against a bright sky, motion frozen, photorealistic, no text.”
| Qwen | FLUX |
|---|---|
 |
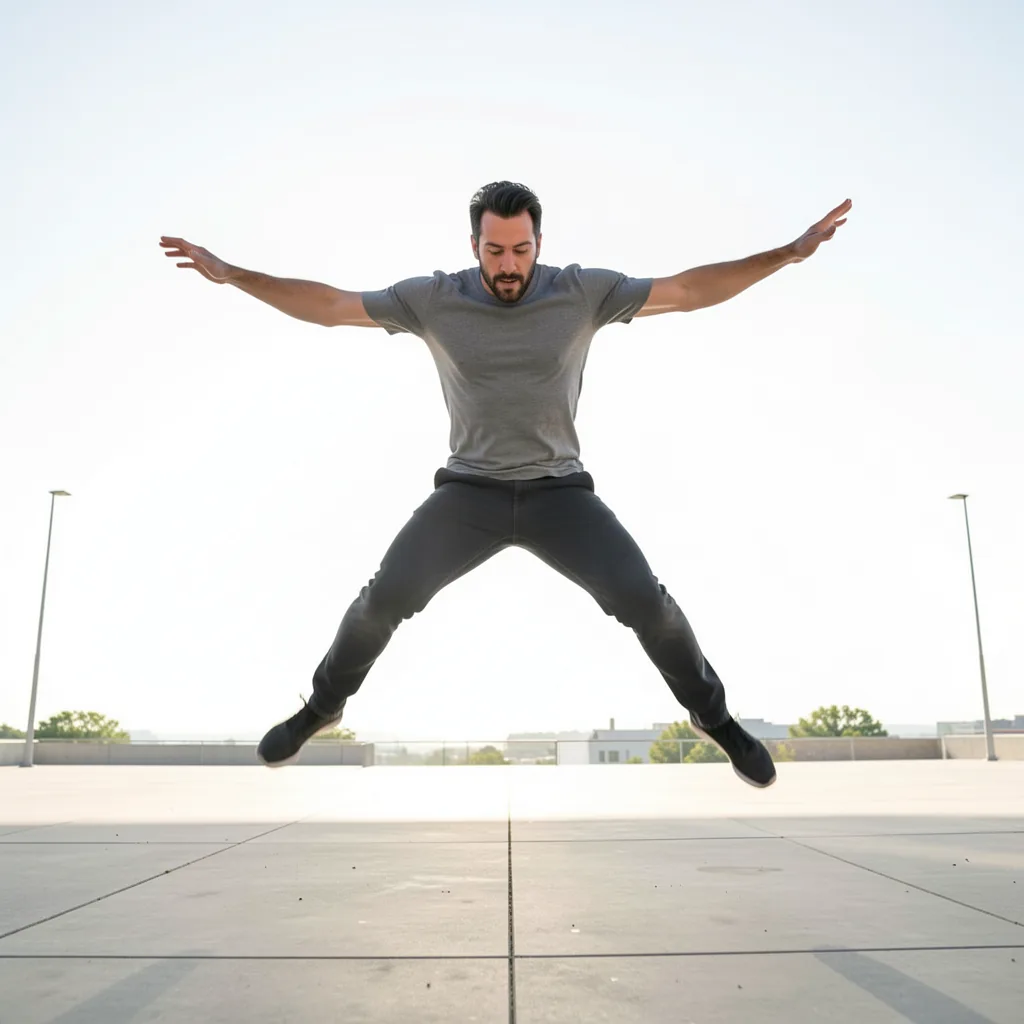 |
| Airborne, ground shadow present | No shadow — reads as pasted in |
Action & expression: a tie, given to FLUX. The laughing shots are a dead tie and both are excellent — real teeth, real crow’s feet. The jump splits the other way on each axis: Qwen’s man casts a proper ground shadow and reads as airborne, but has three legs (two shoes on his left leg) — a limb-count failure the first scoring pass missed. FLUX’s jumper has the right number of limbs but no shadow at all, so he reads as pasted onto the plaza, with an over-long right arm. One model gets the physics right, the other the anatomy; neither jump is usable as is.
Slot 7 — Reference-image editing
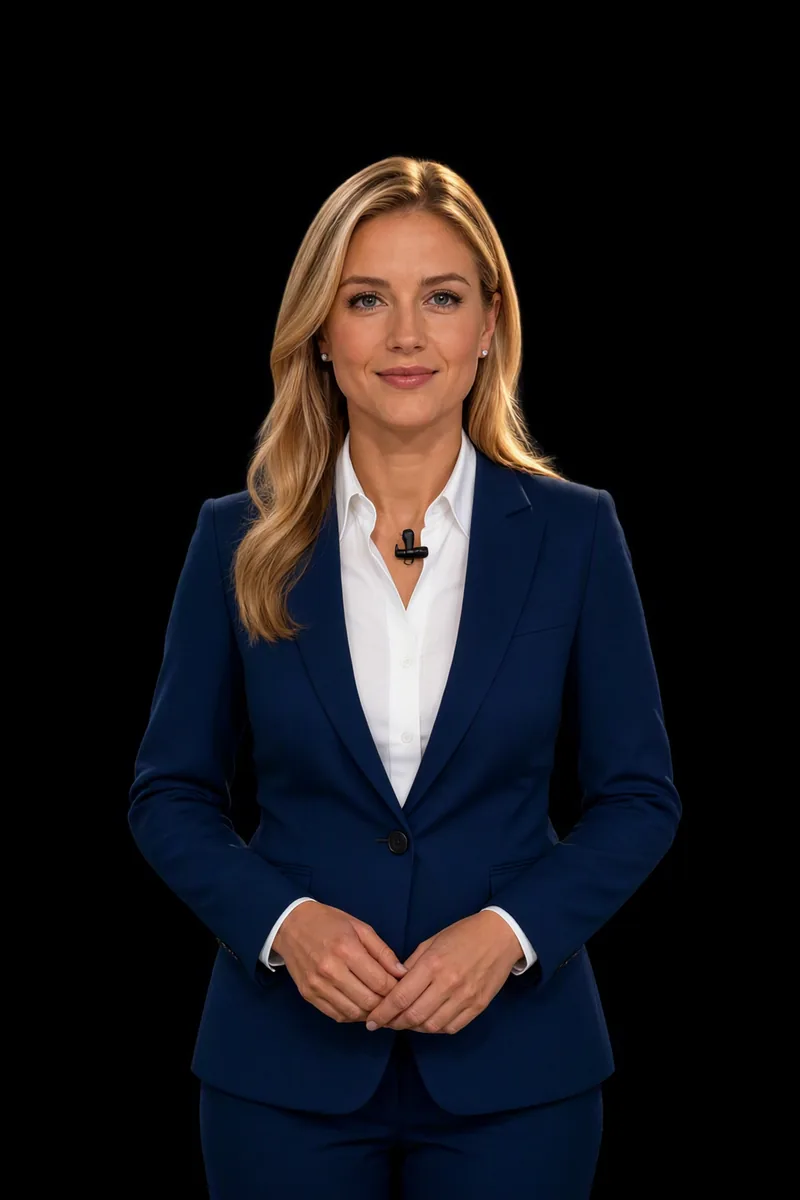
Prompt (s7a, seeds 11 & 202): “Change her outfit to a navy blue tailored blazer with peaked lapels worn open over a crisp white shirt. Keep her face, hair, pose, expression, lapel mic and the plain background exactly the same.”
| Qwen | FLUX |
|---|---|
 |
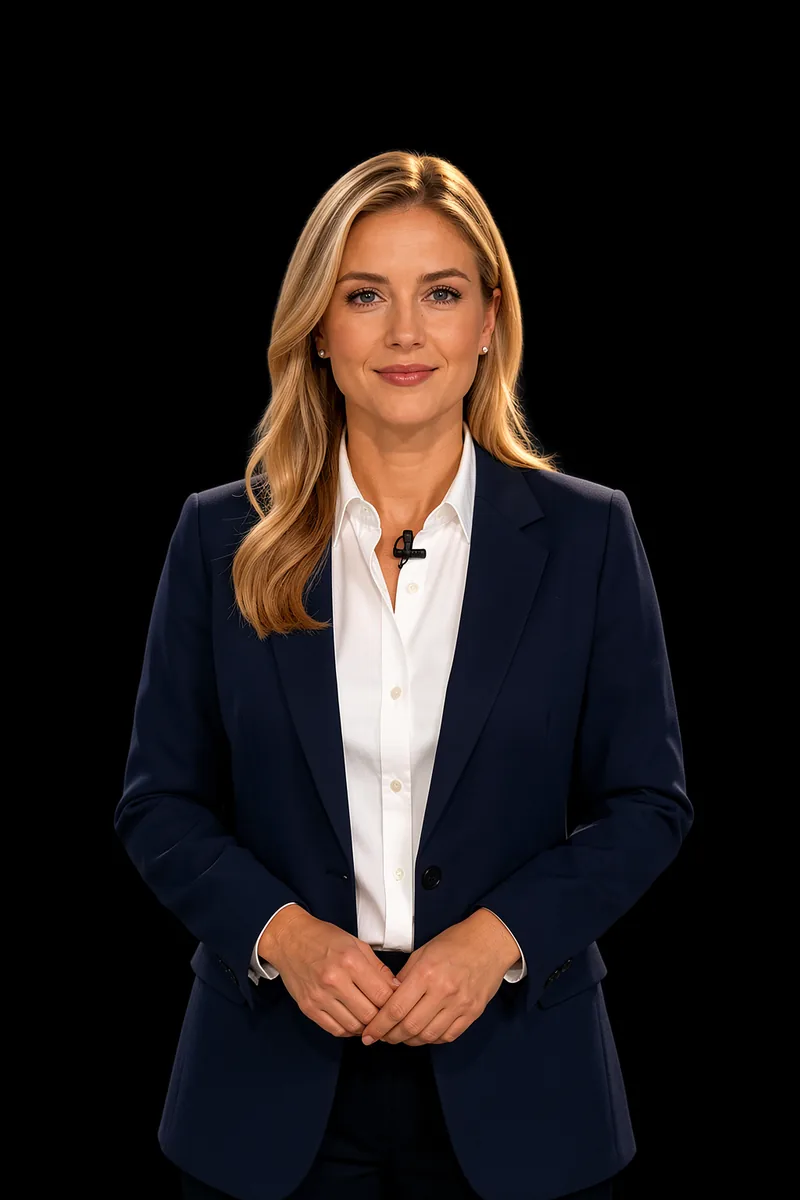 |
| Identity 5/5, but blazer buttoned shut | Blazer open as asked, but identity 3/5 |
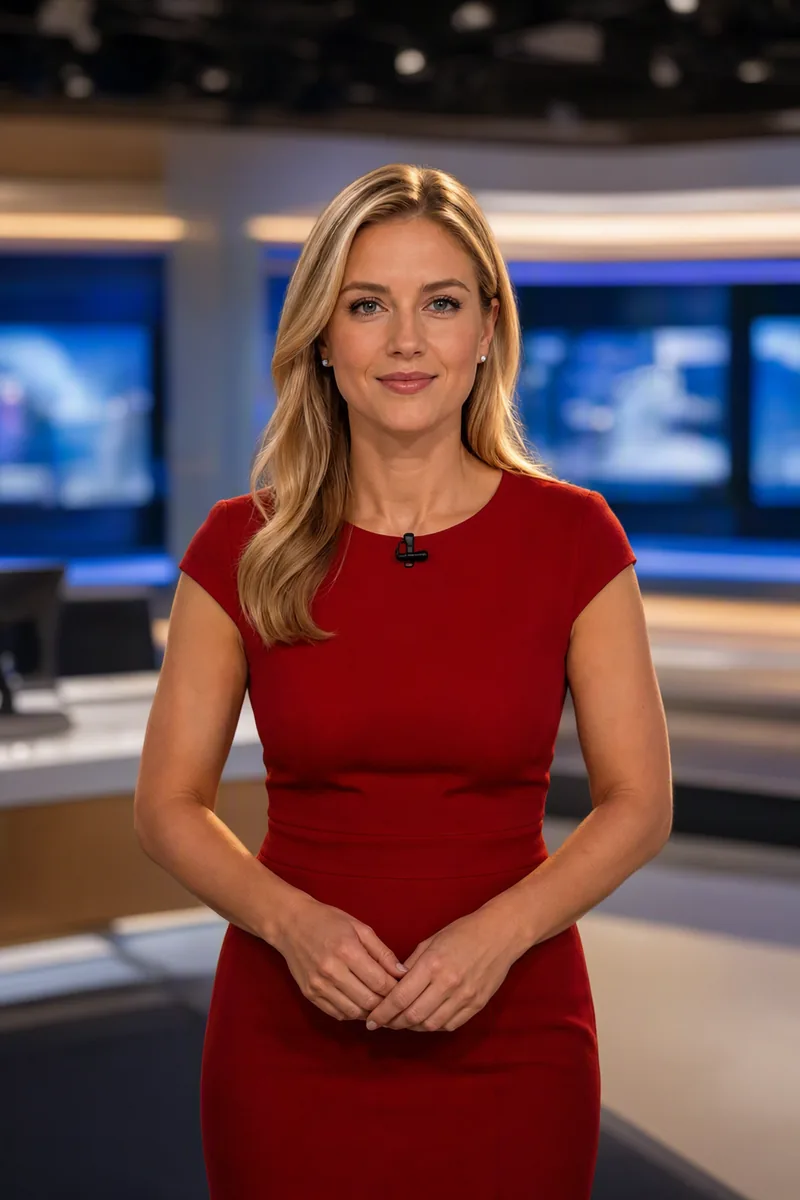
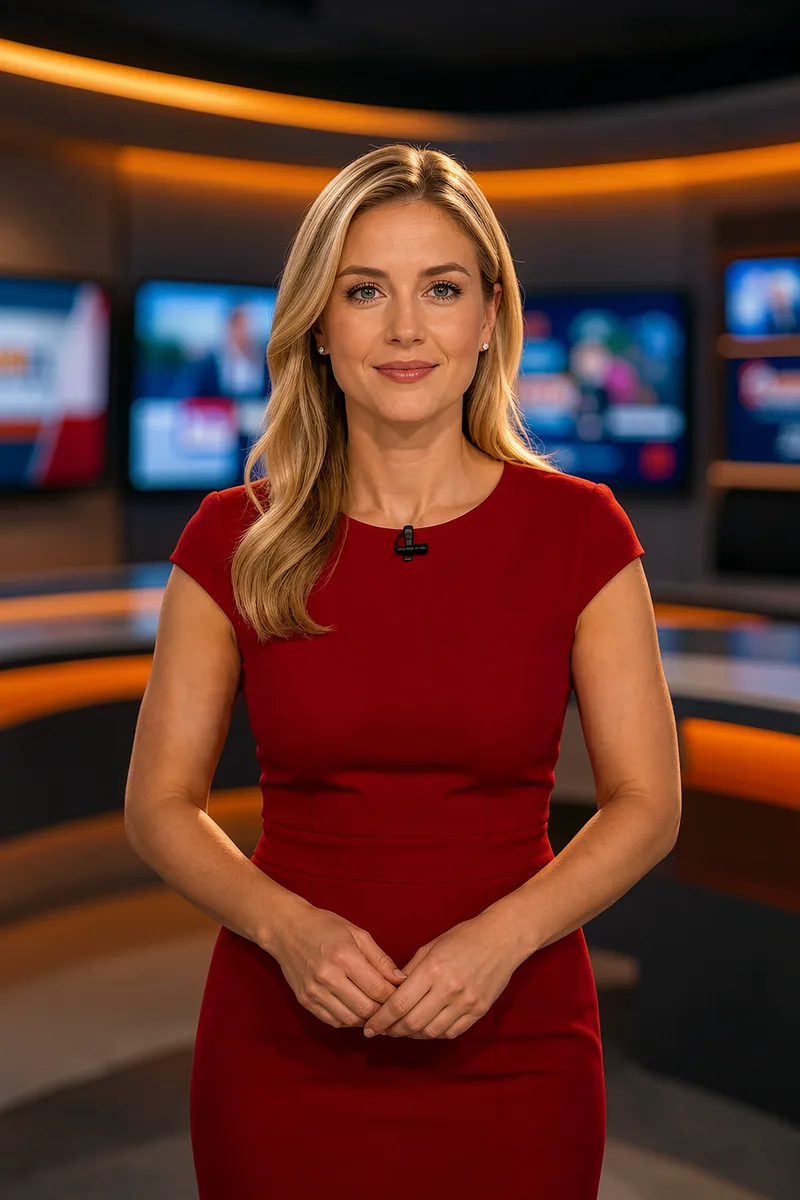
Prompt (s7b): “Replace the background behind her with a modern television newsroom: softly blurred wall monitors, a news desk edge and warm studio lighting. Keep her face, hair, outfit, pose and expression exactly the same.”
| Qwen | FLUX |
|---|---|
|
|
| Identity 5/5, dress/pose untouched | Identity 3/5, face re-made-up |
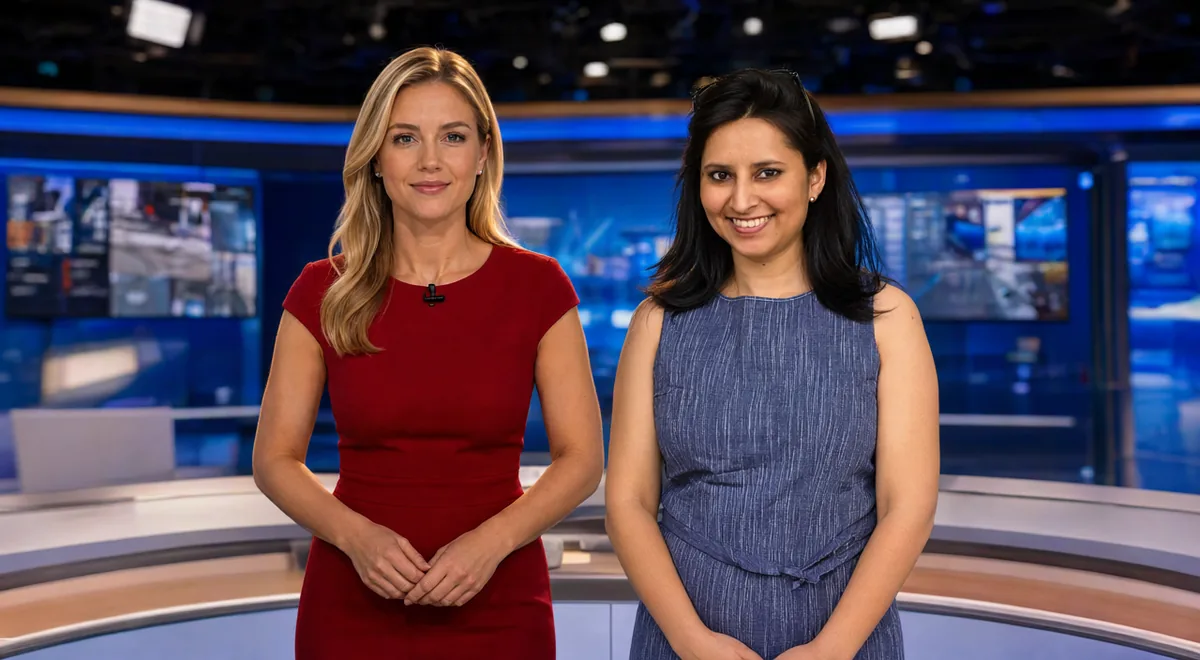
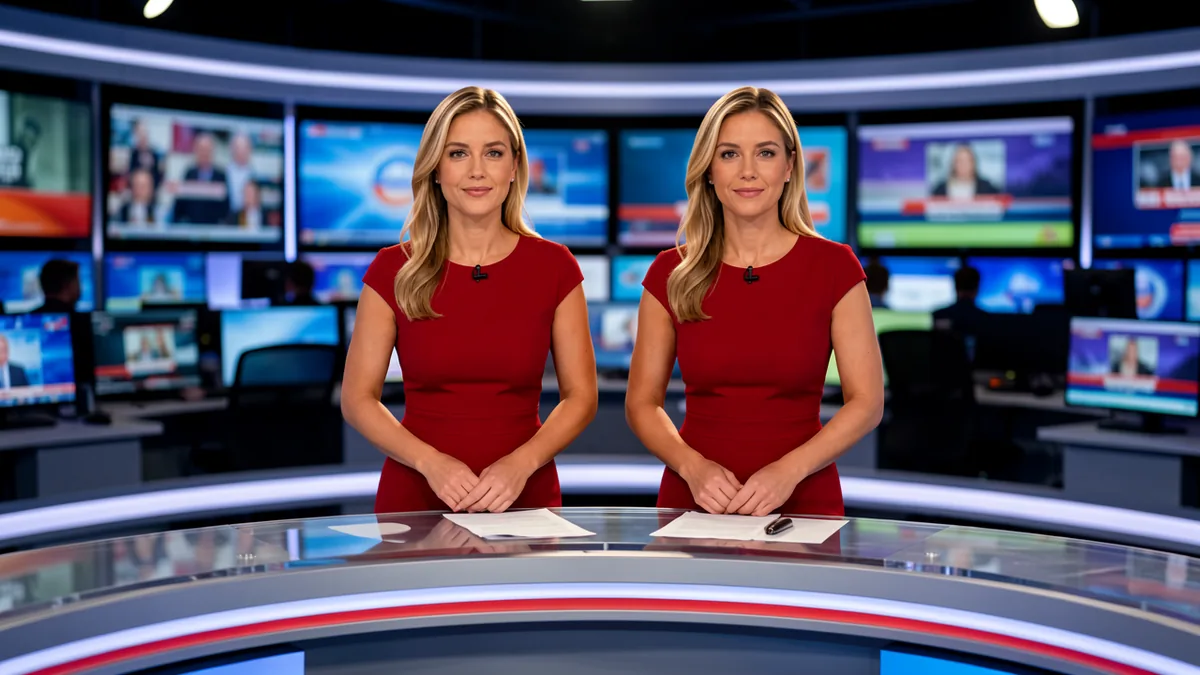
Prompt (s7c): “Two women standing side by side behind a modern television news desk… The woman on the left is the person from the first reference image and the woman on the right is the person from the second reference image. Preserve both faces, hairstyles and skin tones exactly.”
| Qwen | FLUX |
|---|---|
|
|
| Sarah left, Anjali right — both recognisable | Sarah twice — single-ref API limit |
Identity close-up
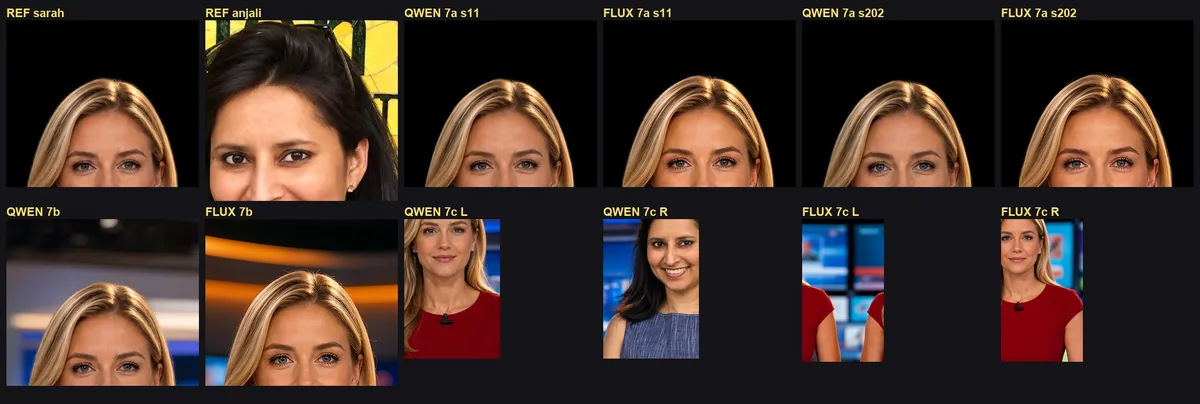
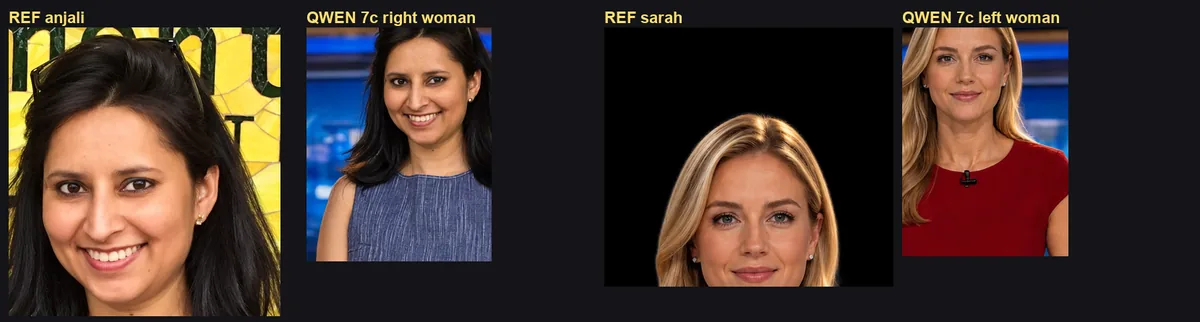
Verdict: split — and the split is the useful result.
- Identity: Qwen 5/5, FLUX 3/5. Across three single-reference edits at two seeds, Qwen kept Sarah’s face essentially unchanged; FLUX re-made her eyes and widened her face every time. This reverses an earlier finding that Qwen beautifies — in this run FLUX was the beautifier.
- Instruction-following: FLUX 5/5, Qwen 3/5. “Worn open over a crisp white shirt” — FLUX opened it; Qwen buttoned it shut at both seeds.
- Multi-reference: Qwen only. Given Sarah + Anjali, Qwen placed two genuinely different, genuinely recognisable women at one desk (Anjali near-exact). FLUX produced Sarah twice. This is a capability gap, not a quality gap — the task is not expressible through FLUX’s edit endpoint.
Category means 4.38 vs 4.06.
Slot 8 — RGBA / transparent output
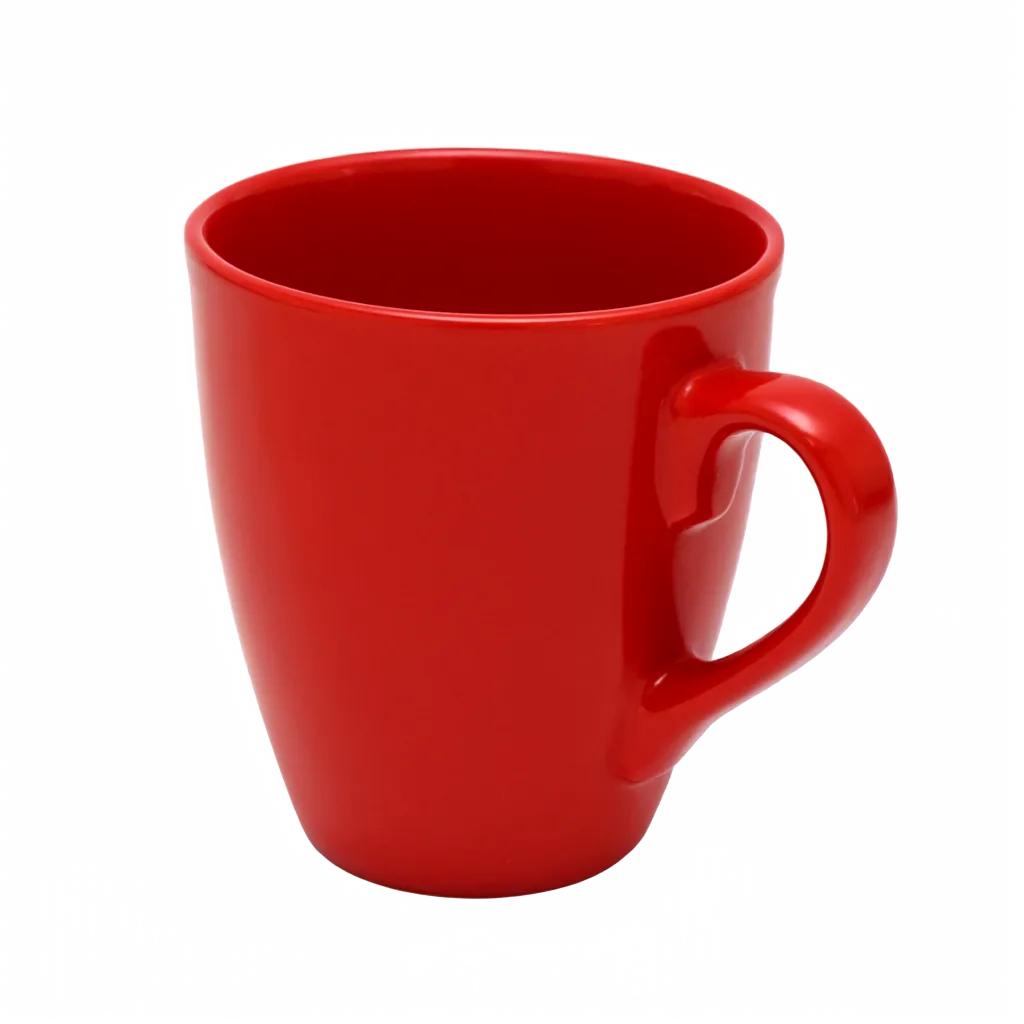
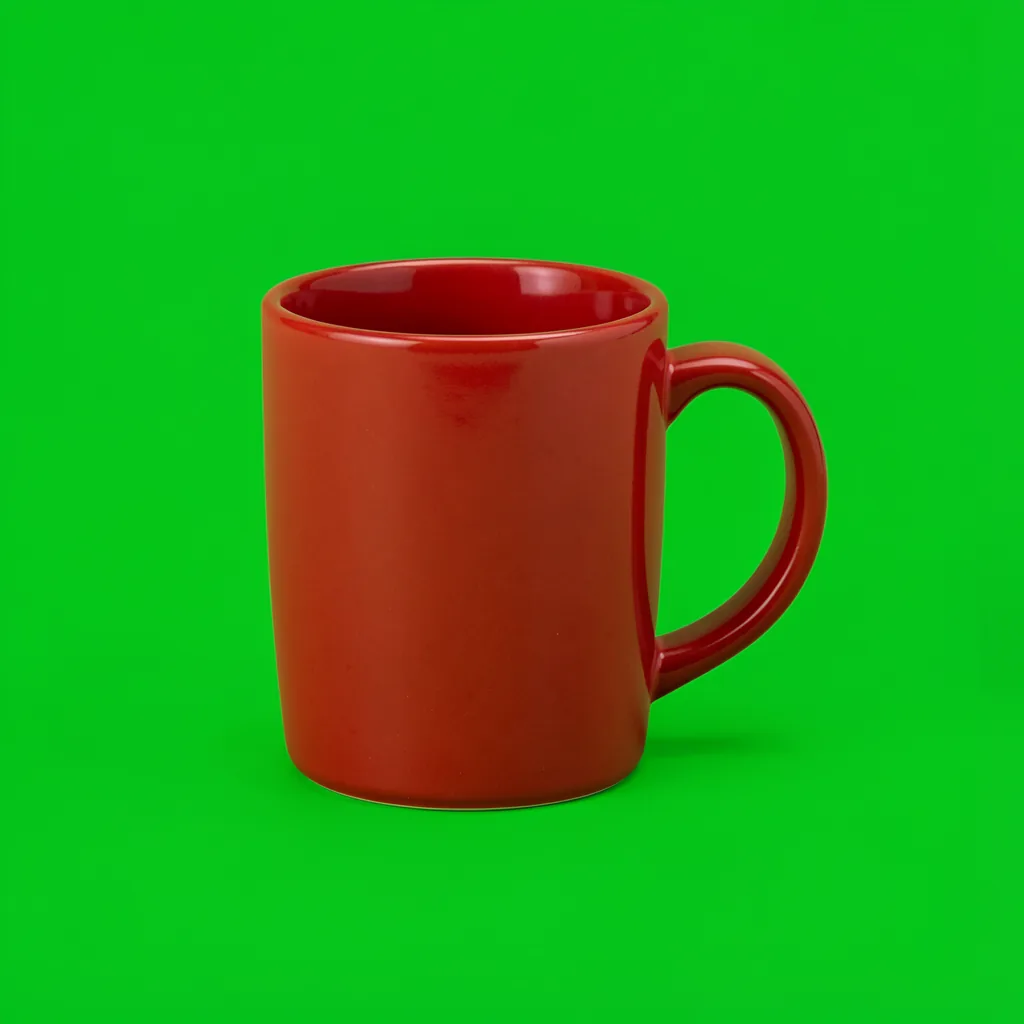
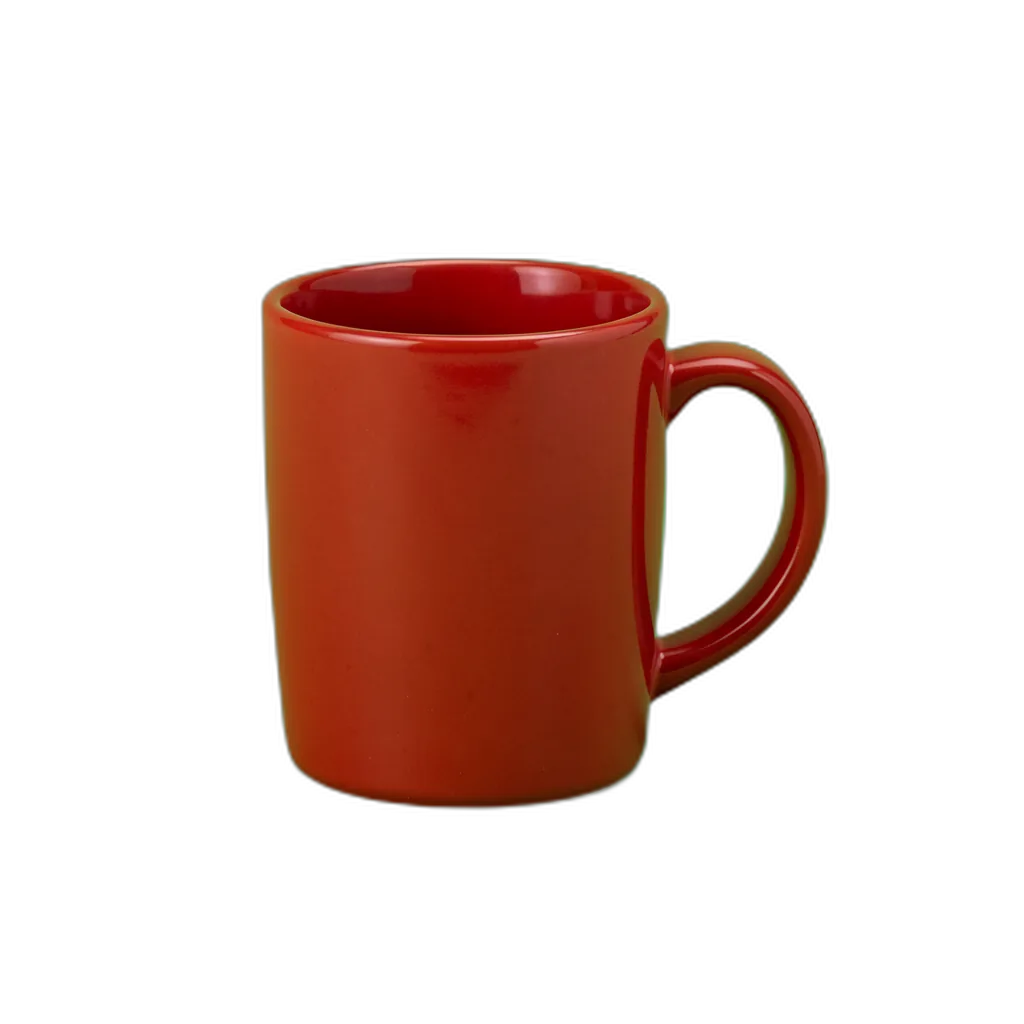
Prompt (s8a): “A single red ceramic coffee mug, product photograph, studio lighting, seen at a slight three-quarter angle with the handle to the right.” — Qwen got the literal transparency wrapper; FLUX got the same subject on flat chroma-green for
rembg.
| Qwen (native alpha) | FLUX (green) | FLUX + rembg |
|---|---|---|
|
|
|
| Native one-pass RGBA, no spill | Chroma-green field | Green fringe on handle/rim |
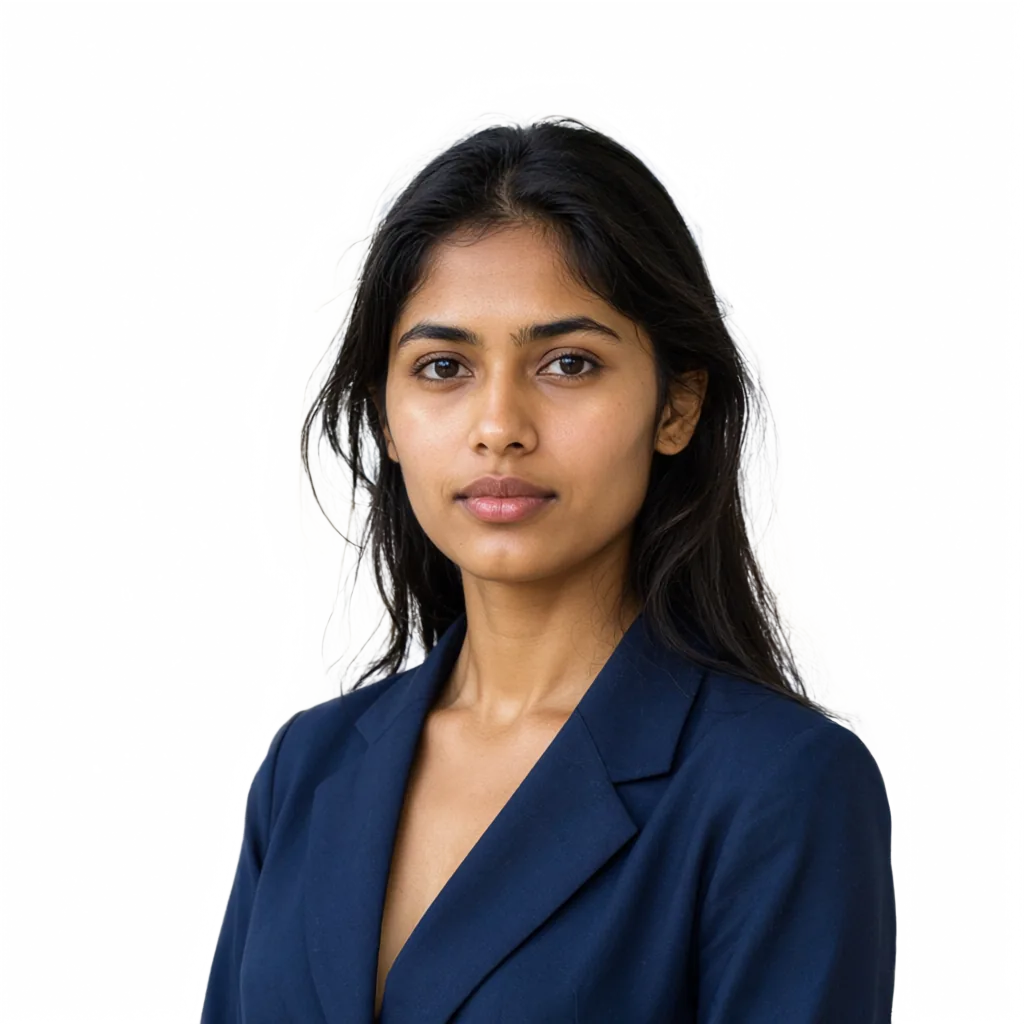
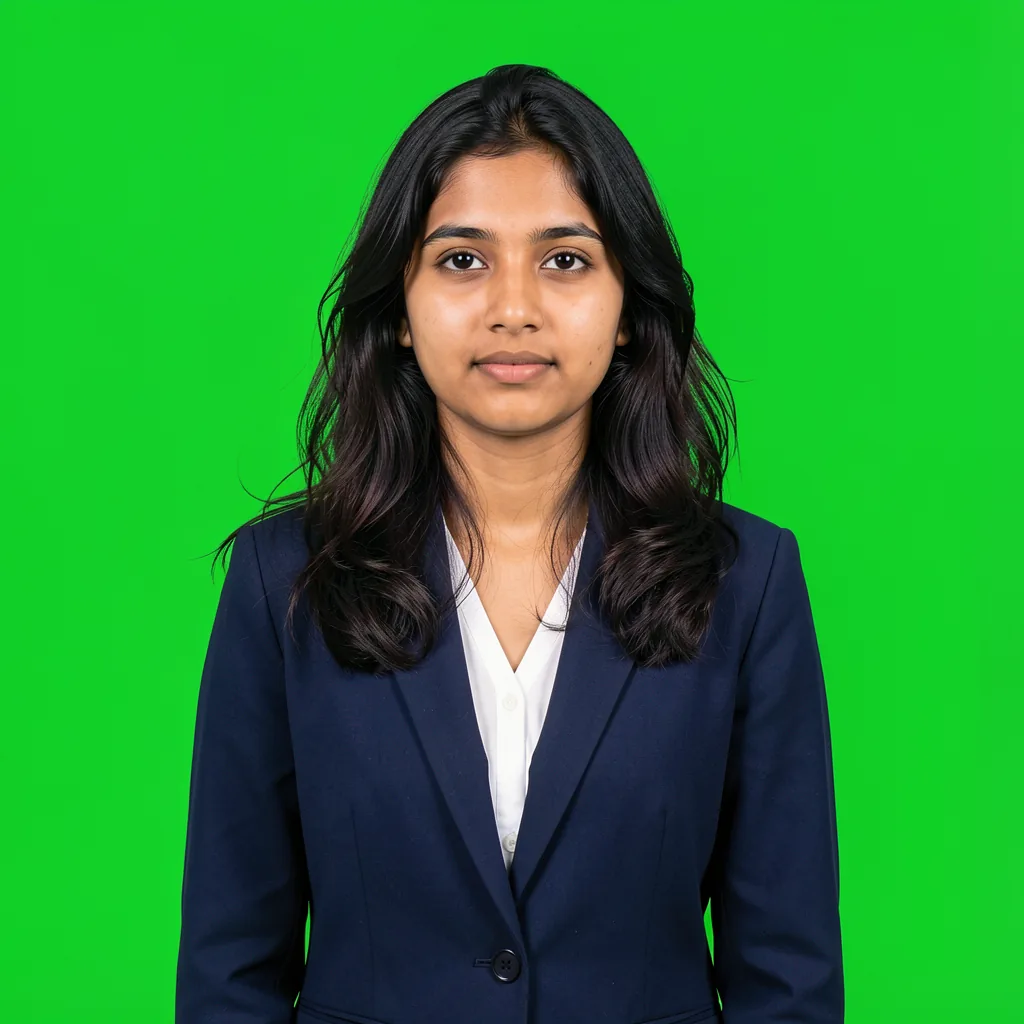
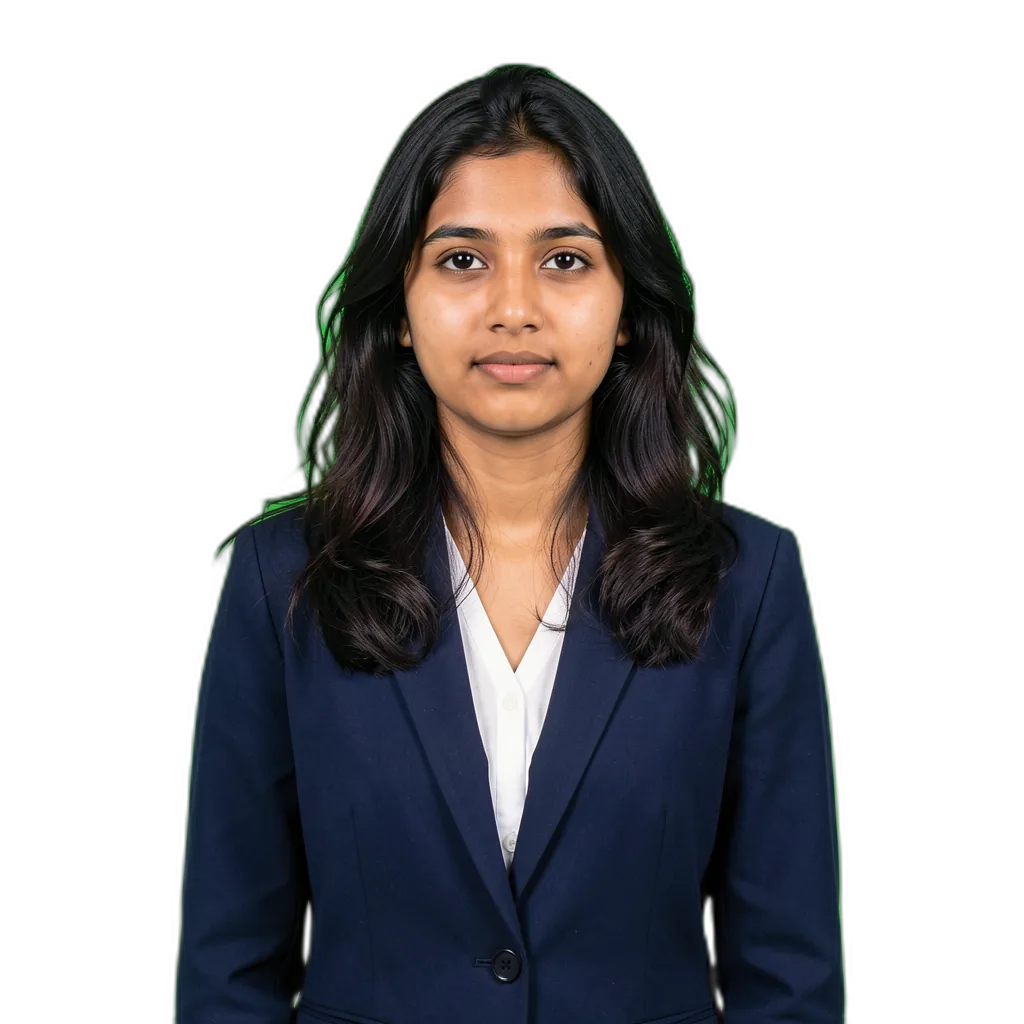
Prompt (s8b): “A cutout of a young Indian woman in a navy blazer standing and facing the camera, waist up, loose dark hair with fine flyaway strands at the edges.”
| Qwen (native alpha) | FLUX (green) | FLUX + rembg |
|---|---|---|
|
|
|
| Real alpha, soft edge | Chroma-green field | Green halo all around the hair |
Verdict: Qwen wins on the thing that matters. Qwen emits real alpha in one pass with no colour contamination. FLUX + rembg leaves a visible green fringe on the mug handle and a green halo around the hair — unusable without a despill pass. Two measured caveats on Qwen:
- Its “transparent” background is alpha 1–7, not 0,
for ~52–55% of the image (from
alpha_stats.json). Composite it over white and you get a faint tint. Fix: thresholdalpha < 8 → 0after generation. - rembg’s matte is geometrically cleaner (77% of the mug image exactly alpha 0) and keeps slightly more flyaway hair; Qwen clips fine wisps.
- Confirming an earlier pitfall: every Qwen output is RGBA mode, including the 24 never asked to be transparent — but their alpha sits at 253–255. Check the histogram, never the mode.
4.29 vs 4.00.
Slot 9 — Aspect ratios & speed
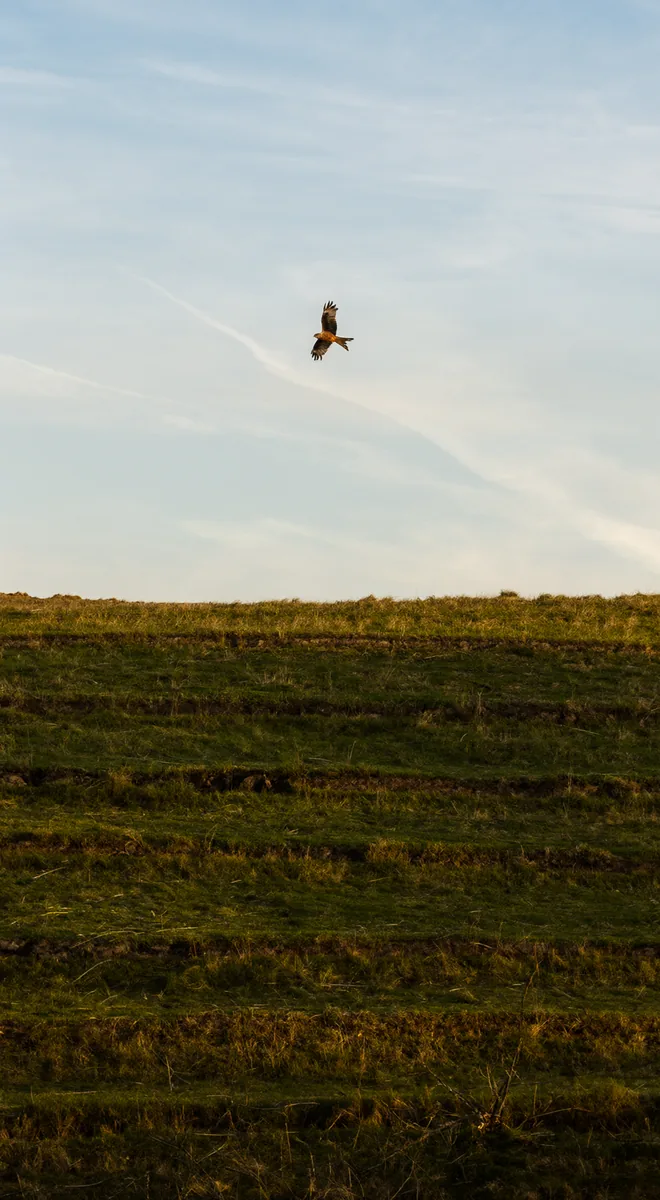
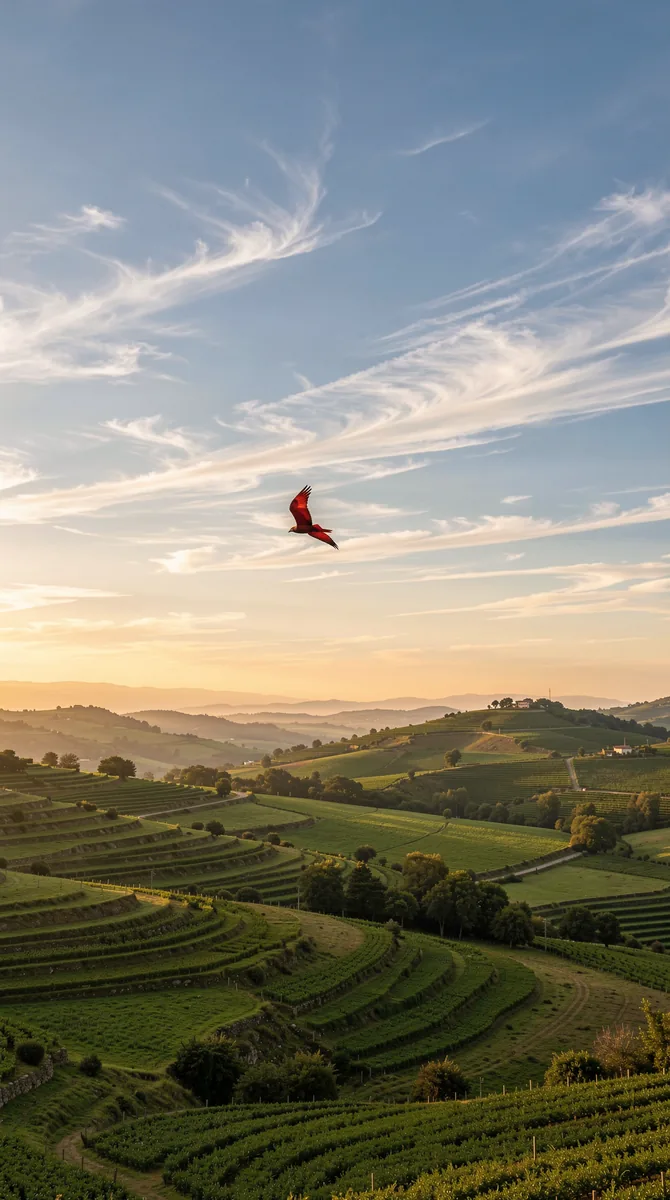
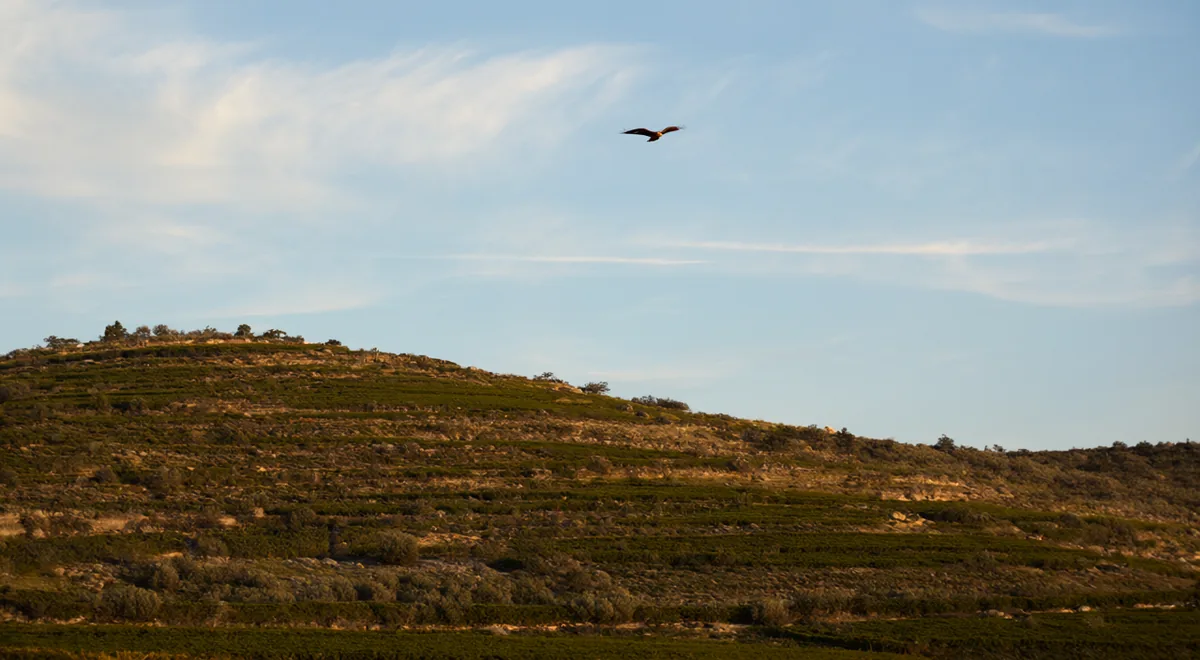
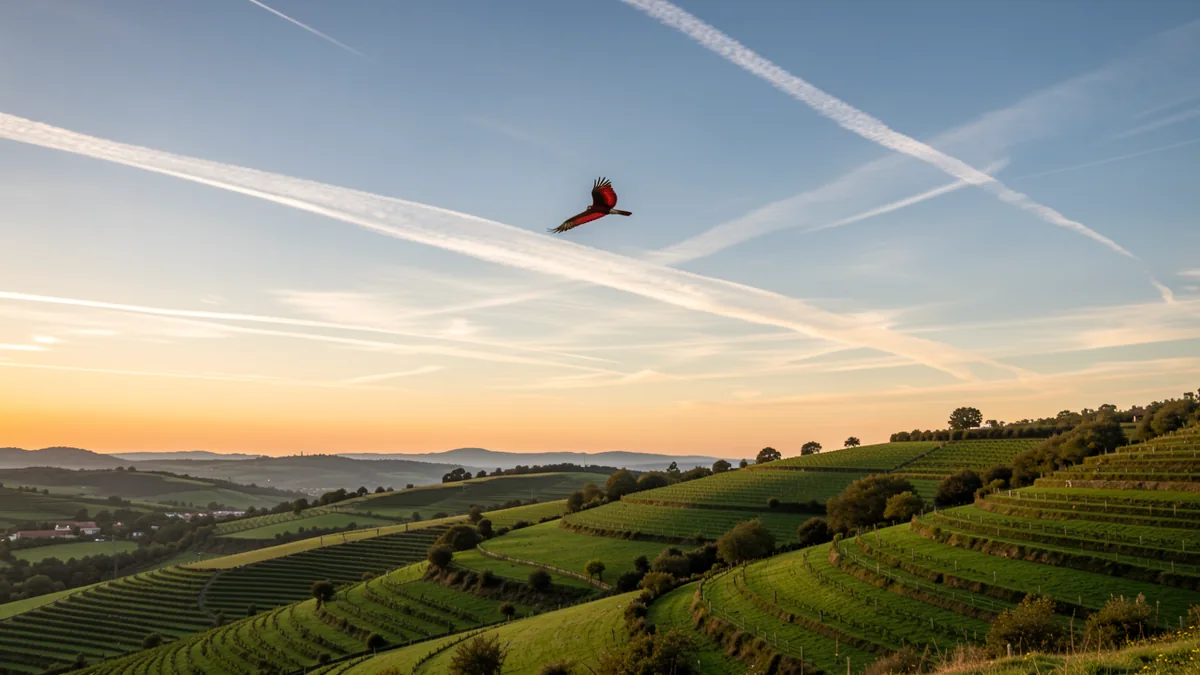
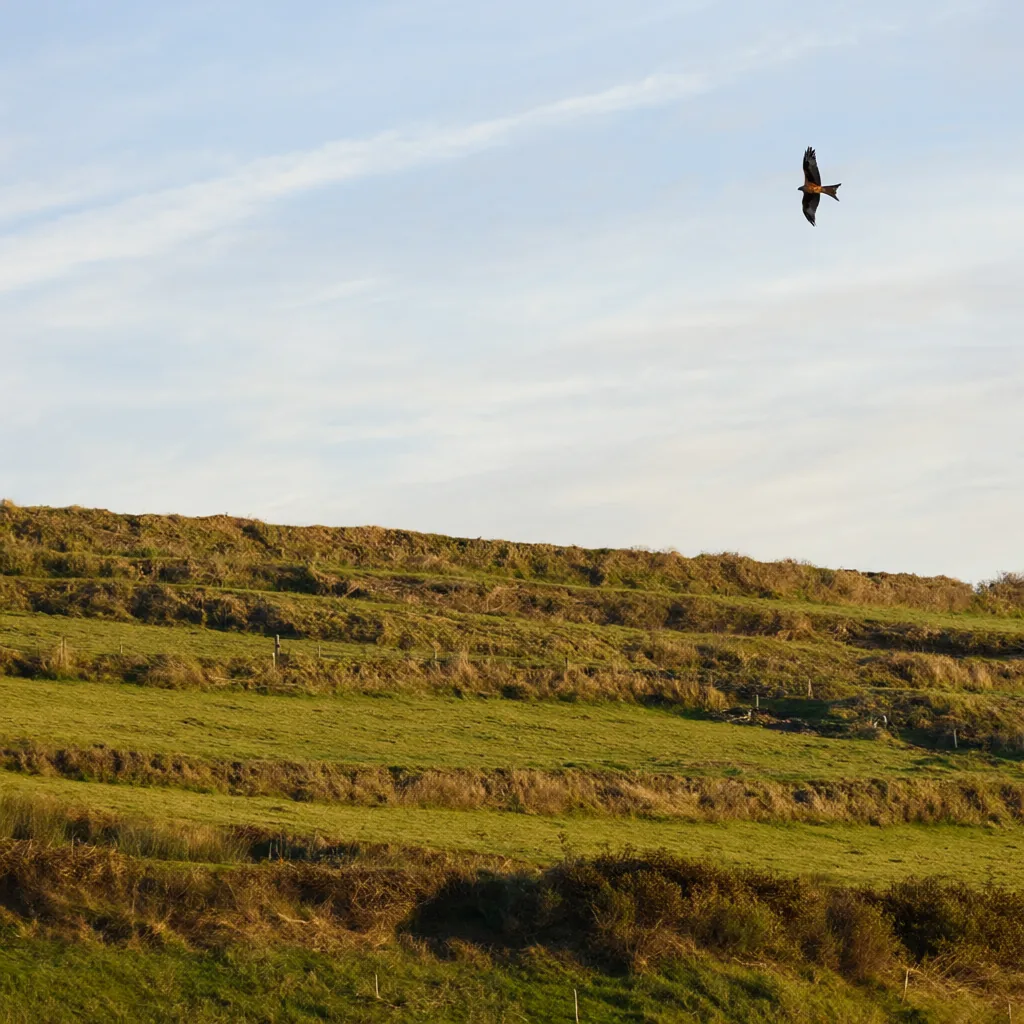
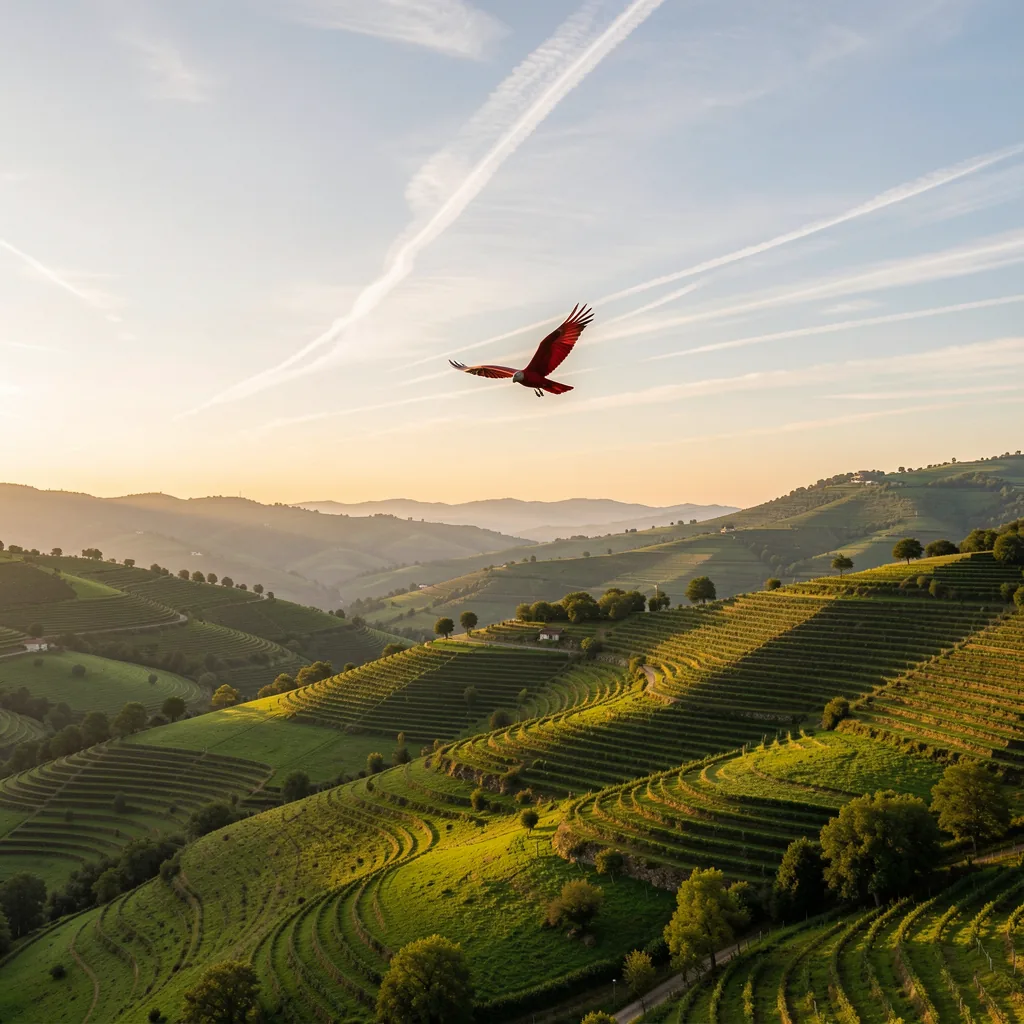
Prompt (s9, three sizes): “A lone red kite flying high above a terraced green hillside at golden hour, thin high clouds, wide natural landscape photograph, photorealistic, no text.”
| Qwen 9:16 (1056×1920, 104 s) | FLUX 9:16 (1072×1920, 231 s) |
|---|---|
|
|
| Dry brown hillside, near-empty | Terraced green hillside, golden hour |
| Qwen 16:9 (1280×704, 46 s) | FLUX 16:9 (1280×720, 71 s) |
|---|---|
|
|
| Same dry hillside miss | Textbook rendition |
| Qwen 1:1 (1024×1024, 52 s) | FLUX 1:1 (1024×1024, 54 s) |
|---|---|
|
|
| Greener, still not terraced | Best image of the three |
Verdict: FLUX, badly. Same prompt, three ratios;
FLUX gave terraced green hillsides at golden hour in all three. Qwen
gave dry brown hillsides with barely any terracing and, at 9:16, a
near-empty frame. Both read “red kite” as the bird rather than a toy —
fair, the prompt is ambiguous — but only FLUX made it red. Qwen’s speed
at 9:16 is the one bright spot (104 s vs 231 s).
3.56 vs 5.00.
Slot 10 — Prompt adherence stress (spatial relations)
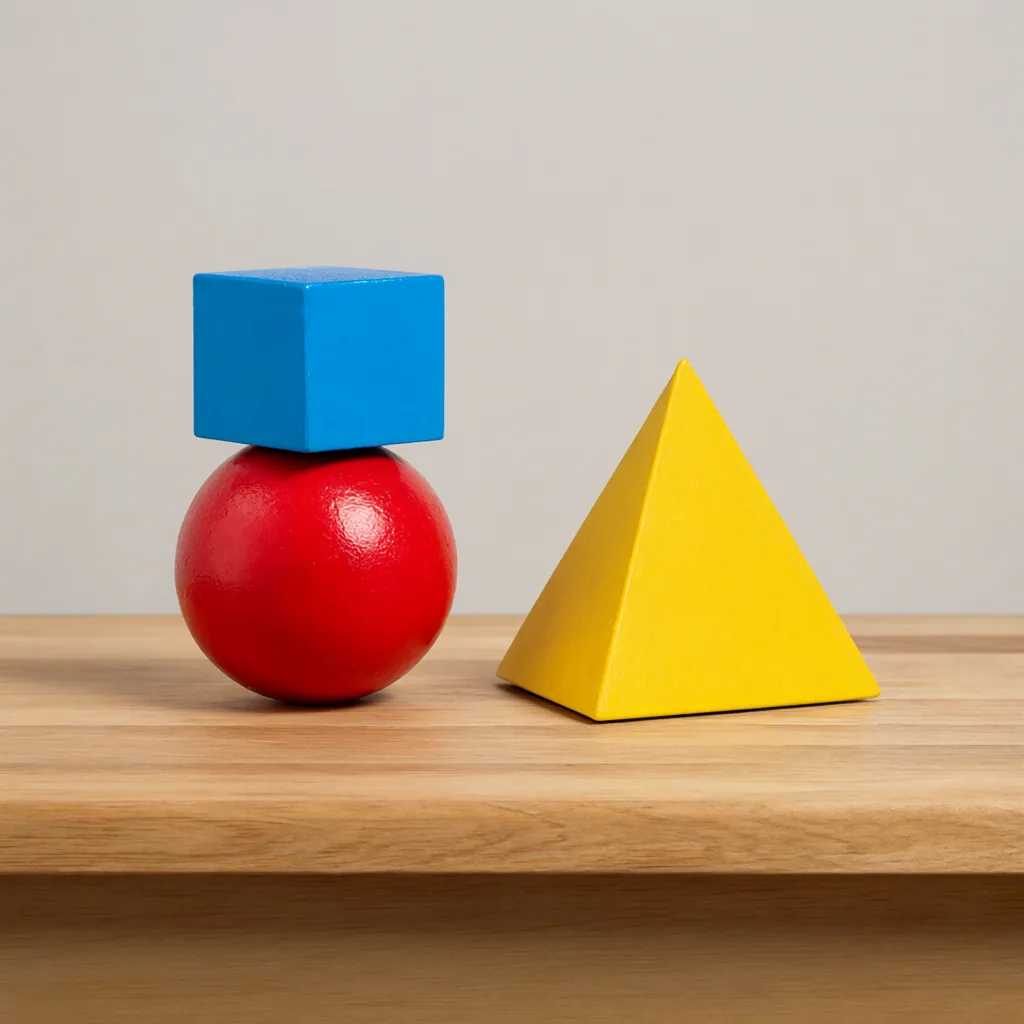
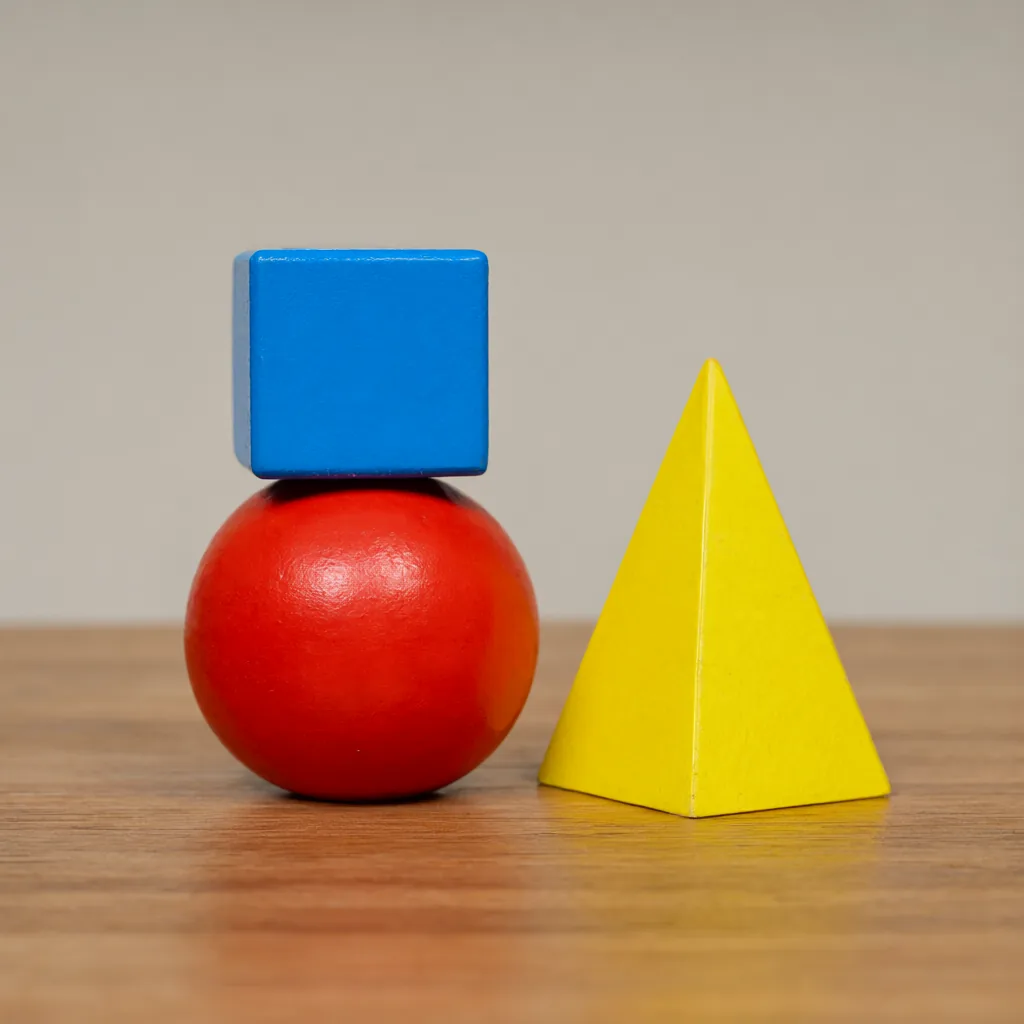
Prompt (s10, seeds 101 & 202): “A blue cube on top of a red sphere, to the left of a yellow pyramid, on a wooden table, no other objects. Plain neutral studio background, product photograph, photorealistic.”
| Qwen | FLUX |
|---|---|
 |
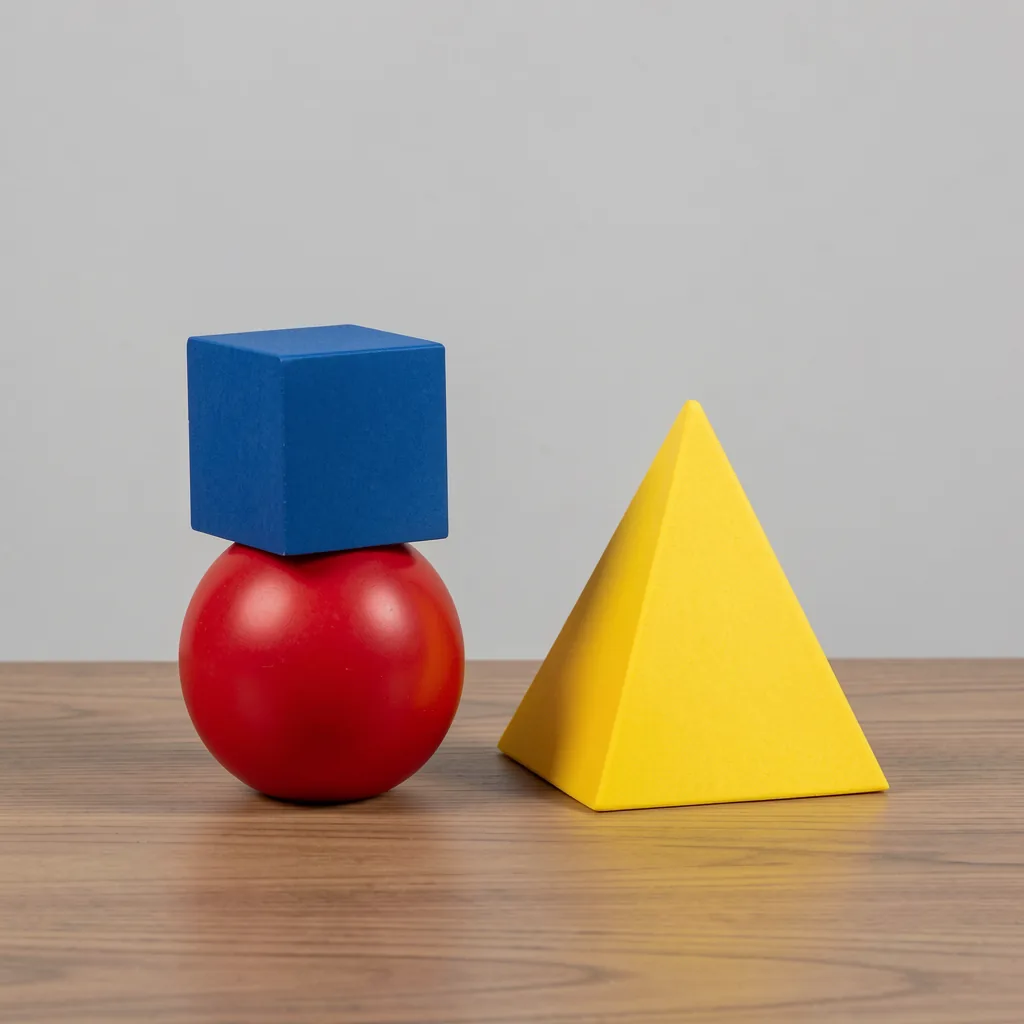 |
| 3/3 relations at seed 101 | 3/3 relations at seed 101 |
 |
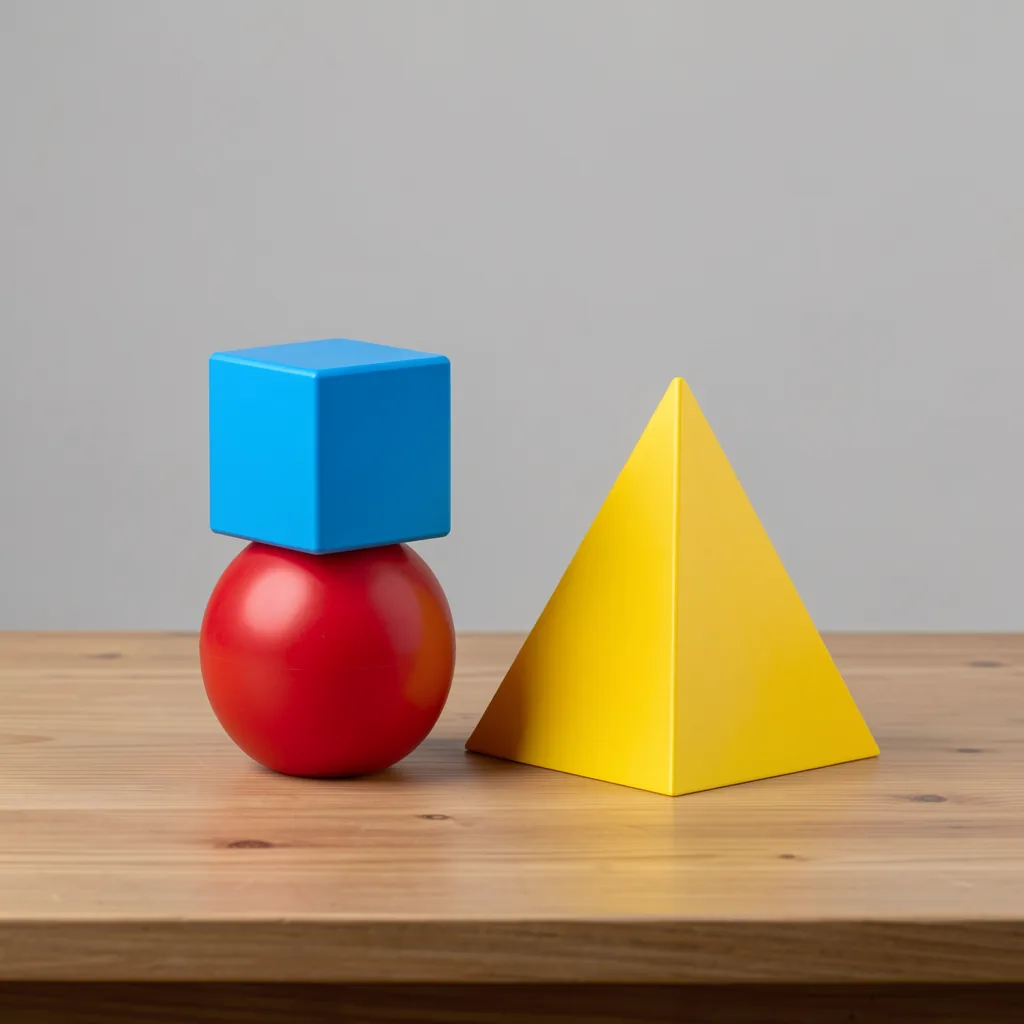 |
| 3/3 relations at seed 202 | 3/3 relations at seed 202 |
5.00 vs 5.00.
4. Timings & memory
Not apples-to-apples: Qwen runs 40 bf16 steps on a GB10, FLUX runs 4 MLX steps on an M3 Ultra.
| Qwen-Image-2.1 | FLUX.2 Klein | |
|---|---|---|
| Median s/image | 51.8 s | 28.2 s |
| Total for 26 images | 1493 s gen + 237 s load = 28.8 min | 1196 s gen = 20.0 min |
| Amortised load per image | 9.1 s | ~0.1 s |
| Peak memory | 38.6 → 46.1 GB | 42.0 → 46.3 GB |
| 1024×1024 t2i | 51.7 s | 22.6–30.3 s |
| 1280×720 t2i | 45.5 s (→ 1280×704) | 21.0 s |
| 1024×1536 edit, 1 ref | 89.3 s | 87.0 s |
| 1080×1920 t2i | 104.4 s (→ 1056×1920) | 231.2 s (→ 1072×1920) |
Three things worth keeping:
- Both models floor requested dimensions — Qwen to ×32, FLUX to ×16.
- FLUX’s wall time is not stable across a long batch. The same 1280×720 job took 21.0 s early in the run and 70.8 s late in the run, with a 231 s tall job in between. Qwen’s per-size timing was flat to ±0.3 s across the whole batch. Budget FLUX’s late batch images at 2–3× the early ones.
- Qwen at 9:16 is 2.2× faster than FLUX despite running 10× the steps. Tall canvases are where the GB10 earns its keep.
5. Licensing
Both models are non-commercial for the weights themselves; the difference is in the outputs. Qwen-Image-2.1 ships under the Qwen Research License Agreement, verbatim from the model card:“You are granted a non-exclusive, worldwide, non-transferable and royalty-free limited license … FOR NON-COMMERCIAL PURPOSES ONLY. You shall not use the Materials for any commercial purpose without obtaining a separate commercial license from us.” — clause 2(a)/2(b)FLUX.2 Klein 9B — the variant in this test — ships under the FLUX Non-Commercial License (the only Apache-2.0 variants in the family are the 4B and 4B Base). Its weights carry the same non-commercial restriction, but the licence explicitly clears the outputs:
“We claim no ownership rights in and to the Outputs. … You may use Output for any purpose (including for commercial purposes).” — clause 2(d)So the practical difference is not “restricted vs unrestricted”. For the model as a commercial engine, both need a licence from their vendor — Qwen Cloud and Black Forest Labs respectively. For the generated images, FLUX’s terms grant commercial use directly while Qwen’s licence grants no such thing. If you need commercial use of the images without a licence negotiation, that is FLUX’s advantage; if you need it from Qwen, it is a commercial-licence conversation. Beyond licensing, FLUX is already deployed here and Qwen is not — a deployment cost, not a capability difference.
6. Final conclusion
Qwen-Image-2.1 is a text-rendering specialist that happens to also do images. FLUX.2 Klein is a general-purpose model with weaker text but broader competence, better realism, and faster median generation.
What the numbers say
- Overall: Qwen 4.49, FLUX 4.19. A 0.30 gap that is almost entirely text rendering.
- Strip the two text slots and FLUX leads. Of the eight remaining categories FLUX wins or ties most of them; Qwen’s non-text wins are narrow (groups, action/expression, reference edits, RGBA).
- Text is the whole story. Qwen renders English letter-perfect and Devanagari correctly; FLUX renders crisp English with single-character slips and Devanagari as confident gibberish.
- FLUX wins realism and speed. Best skin texture in the test, correct landscapes at every aspect ratio, and a 28.2 s median against Qwen’s 51.8 s.
What each model is
| Qwen-Image-2.1 7B | FLUX.2 Klein 9B | |
|---|---|---|
| Strengths | English text, Devanagari, multi-reference identity, native alpha | Photorealism, landscapes, aspect ratios, edit instruction-following, speed |
| Weaknesses | Weak landscapes/aspect ratios, ignores garment-level edit detail, slower median | No Devanagari, single-reference edit API, no alpha, text slips |
| Licence | Research-only weights, no commercial output grant | Non-commercial weights, outputs cleared for commercial use |
Verdict in one line
Two complementary specialists: Qwen owns text and identity preservation, FLUX owns realism and throughput. Neither dominates — the higher overall score rests almost entirely on two text slots.
Appendix — raw files
| Path | Contents |
|---|---|
slot01_text_english/ … slot10_prompt_adherence/ |
Per-slot qwen_*.png, flux_*.png, sheet_*.png |
slot07_reference_edit/identity_faces.png |
Face crops: refs vs both models |
slot07_reference_edit/identity_multiref.png |
Two-reference identity check |
slot08_rgba/flux_*_rembg.png |
The rembg cutouts |
qwen_raw/, flux_raw/, flux_rembg/ |
Unsorted originals |
refs/ |
The two identity references |
qwen_results.json, flux_results.json, alpha_stats.json |
Machine-readable timings & alpha histograms |
_tables.md |
Full per-image score tables |
matrix.py |
The shared prompt source of truth |